Lecture 6: Multi-Agent: The More the Merrier?
Effective AI use in applied machine-learning projects
The more the merrier, or the messier?
Sixteen Claude agents built a compiler, then got stuck
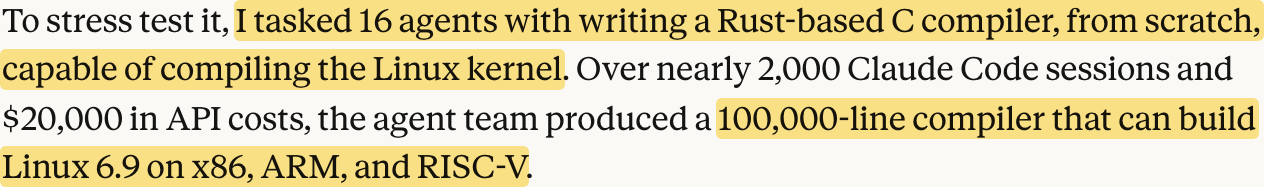
Same agents, same project.
When do more agents help, and when do they make a mess?
…
Outline
A. Multi-agent in practice
B. Dividing the work
C. Coordinating the agents
D. Running and checking the team
Claude’s compiler project split the work by tests and by roles
…
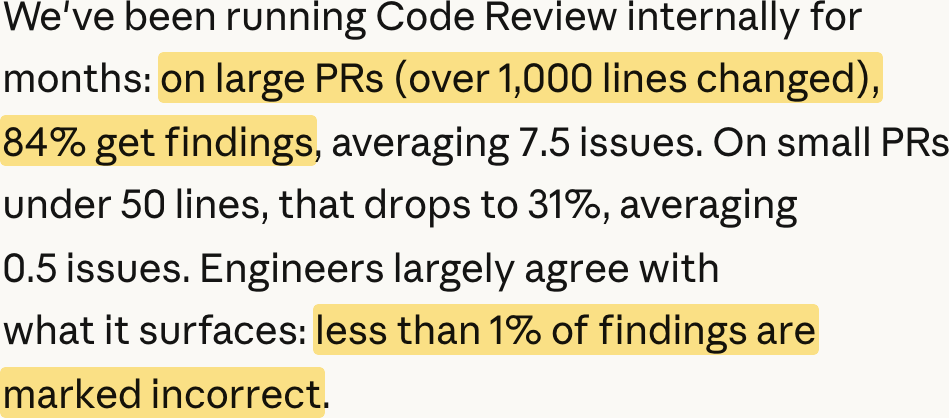
Claude Code Review splits review into finding and checking
Anthropic runs a team of review agents on nearly every internal pull request.
…
Devin Review: a reviewer with no shared context caught about 2 bugs per pull request, 58% severe.
Six weeks later: a bug got past human and agent review
Apr 2026, Anthropic’s postmortem on a Claude Code bug:
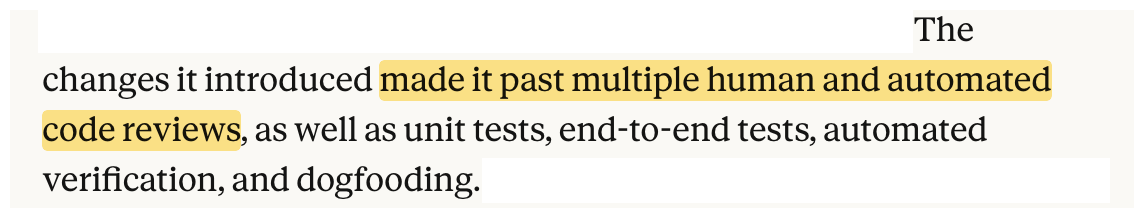
Re-running Code Review on the faulty pull requests:
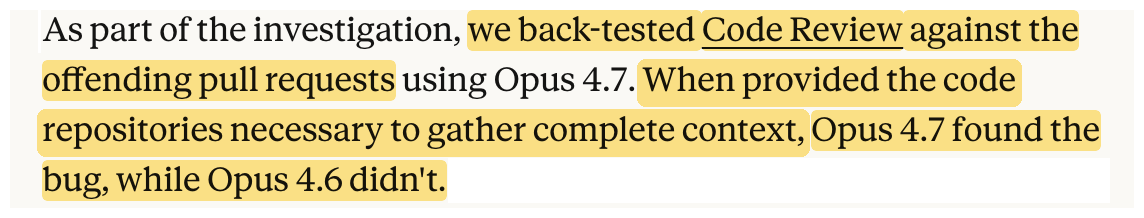
The agent reviewers missed it; a stronger model with the full codebase caught it.
Cursor’s agents queued, dodged hard work, then drifted
First design: agents coordinated as equals through one shared file
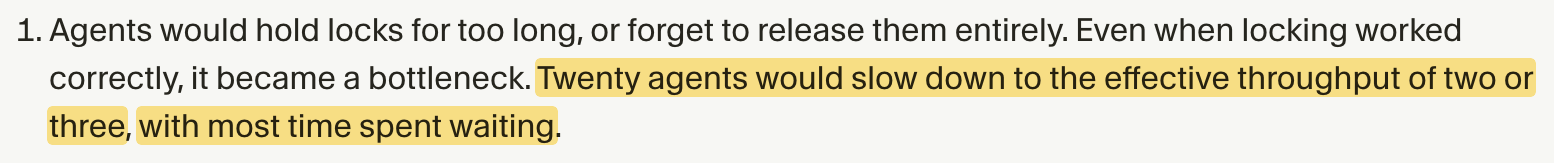
Later, from the engineer who led it
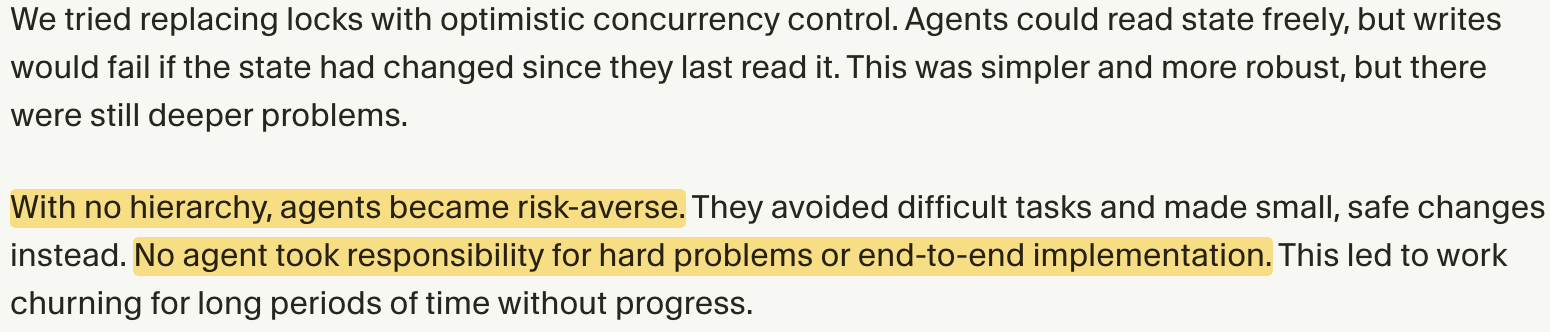
Second design: no locks, and no hierarchy
Cursor’s fix: workers that don’t talk to each other
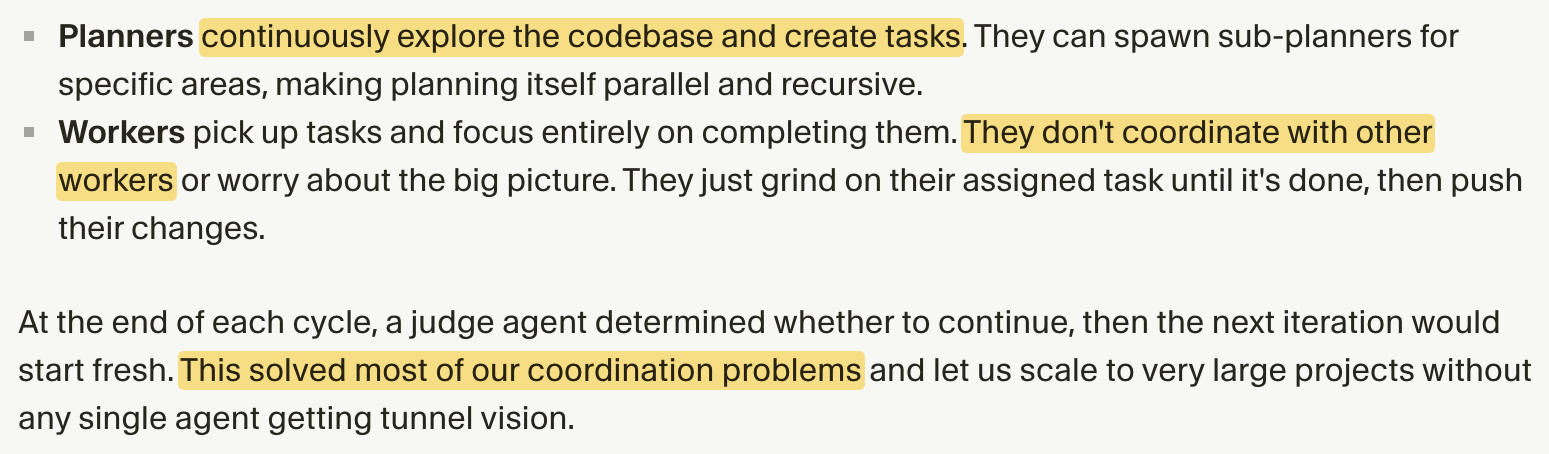
Their third design, after a week of hundreds of agents building a browser from scratch.
Claude Research used the same lead-and-workers design.
After: Cursor dropped its judge, fixed the brief, then added a coordinator
Feb 2026, Cursor’s follow-up post:
The integrator every merge went through:
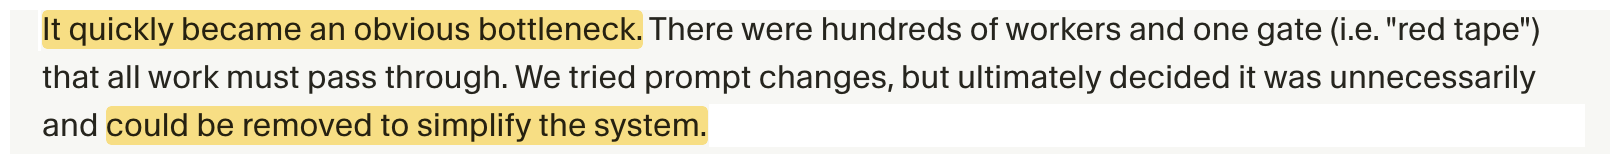
On the library the goal ruled out:
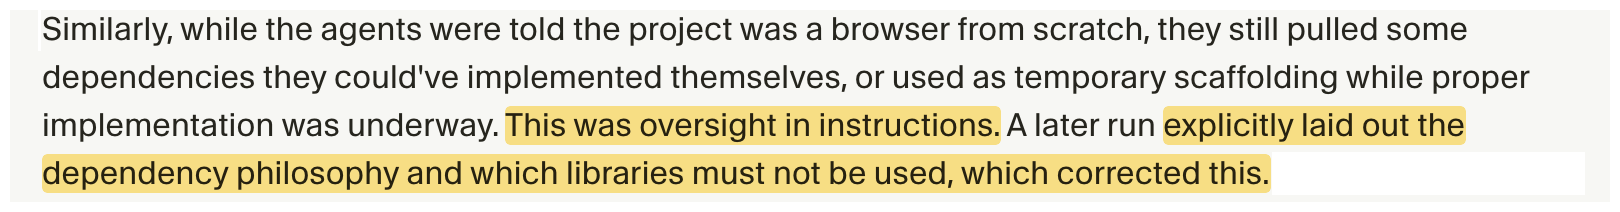
Sep 2026, Cursor Projects:

Kimi’s model learned to split the work itself
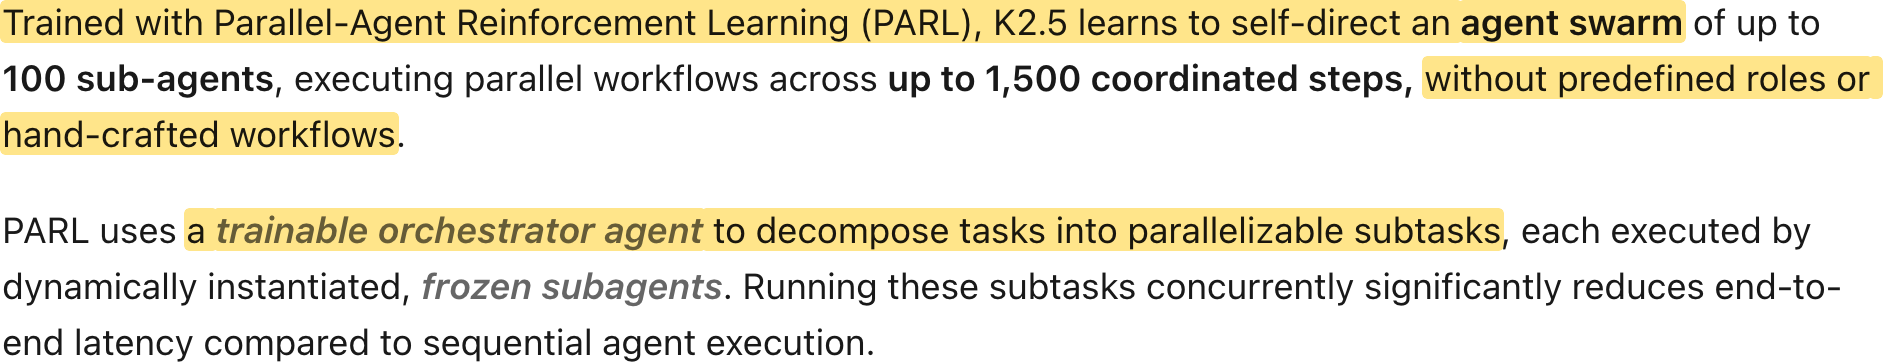
…

By Kimi K2.6 (Apr 2026), the swarm scaled to 300 sub-agents and 4,000 steps.
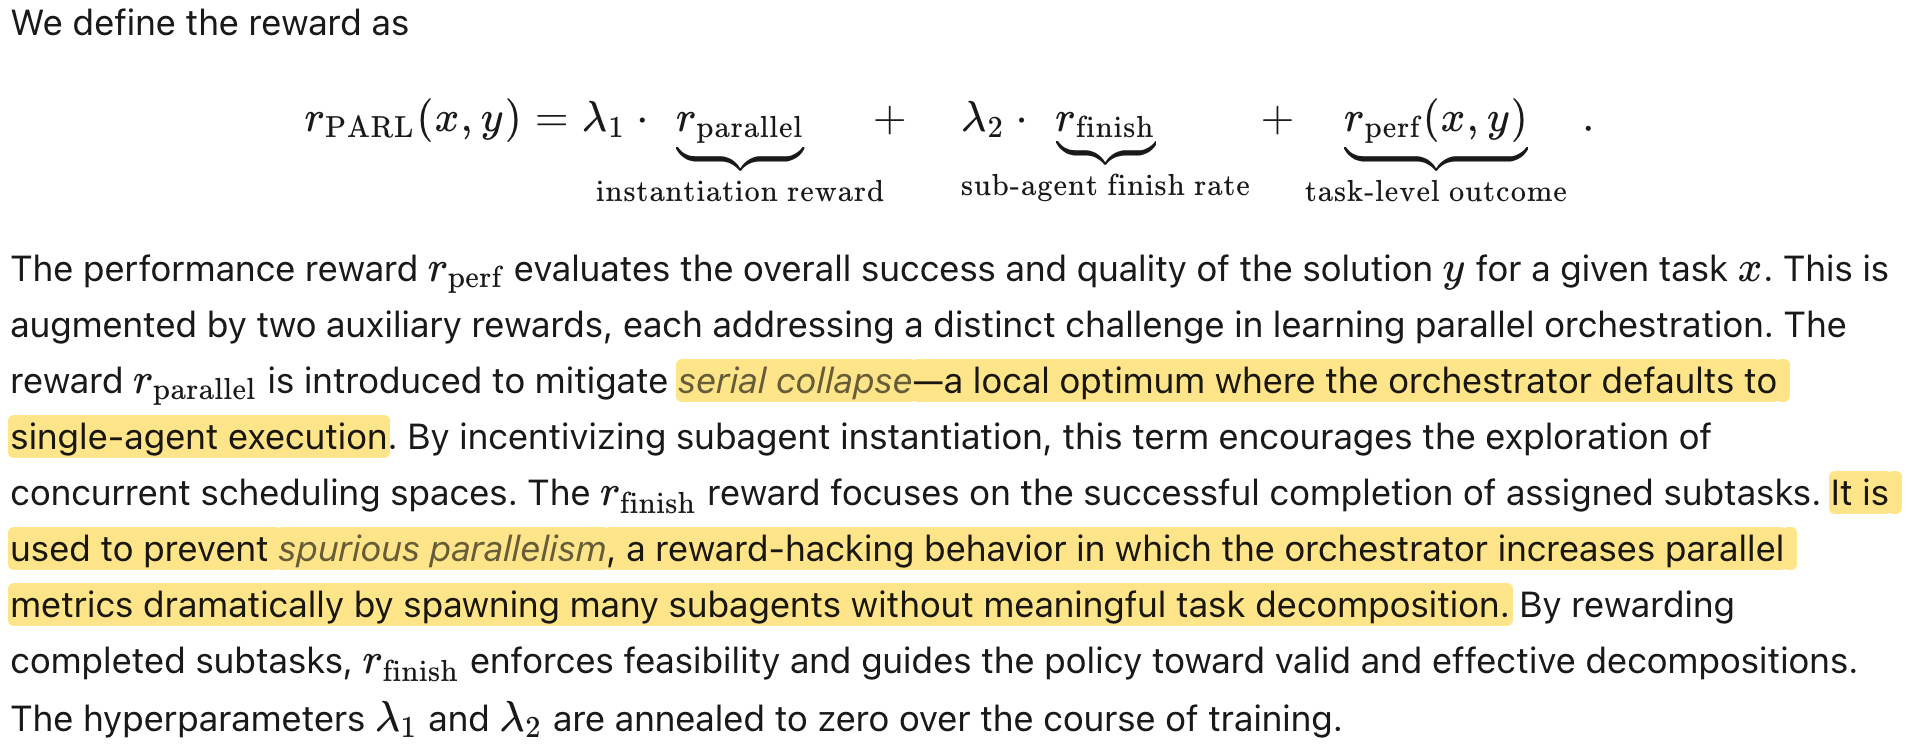
Kimi’s orchestrator failed both ways: no split, or fake splits
The orchestrator’s training reward, from the tech blog:
A manager Devin assumed its child Devins knew what it knew
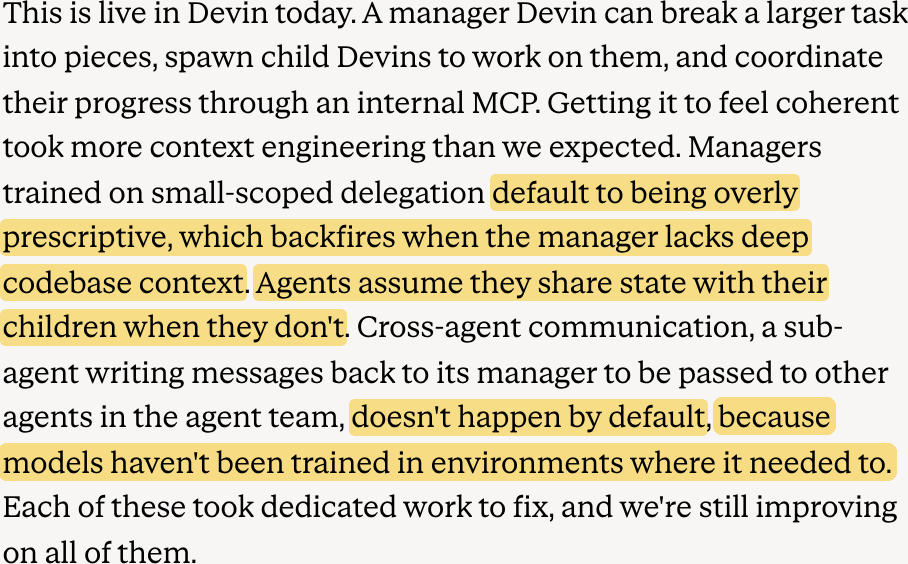
Cognition, maker of the Devin coding agent, on scaling Devin from single tasks to larger projects.
Five months later: Devin’s lead writes each helper a brief
Fusion pairs a lead agent on a frontier model with a cheaper sidekick that writes code.
Sep 2026, Fusion in Devin’s desktop app:
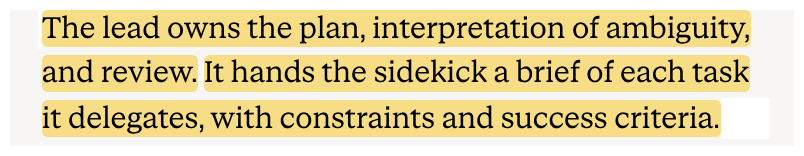
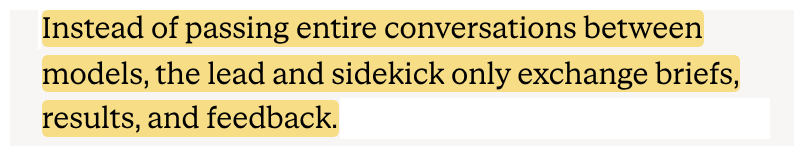
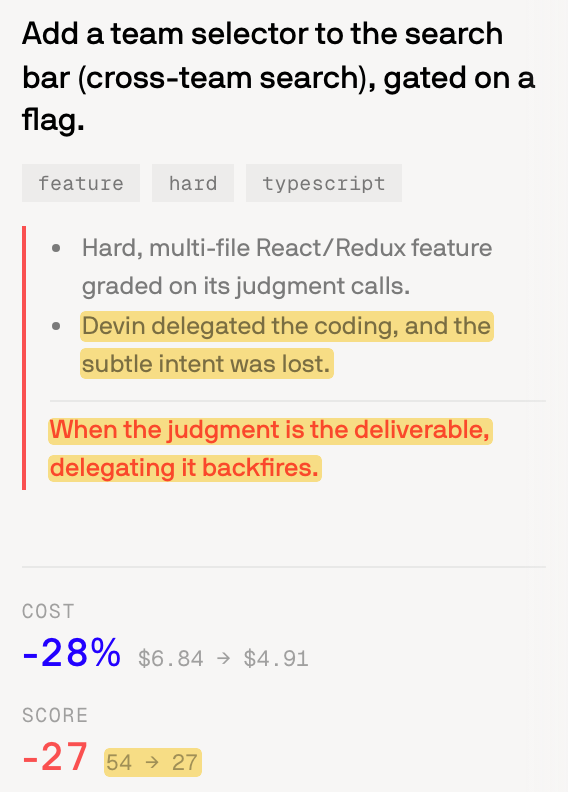
Jun 2026, where handing off failed:
One agent’s cleanup erased the others’ work in a shared folder
A Claude Code user ran several agents in parallel in one working folder.
Splitting the task does not isolate the agents’ writes.
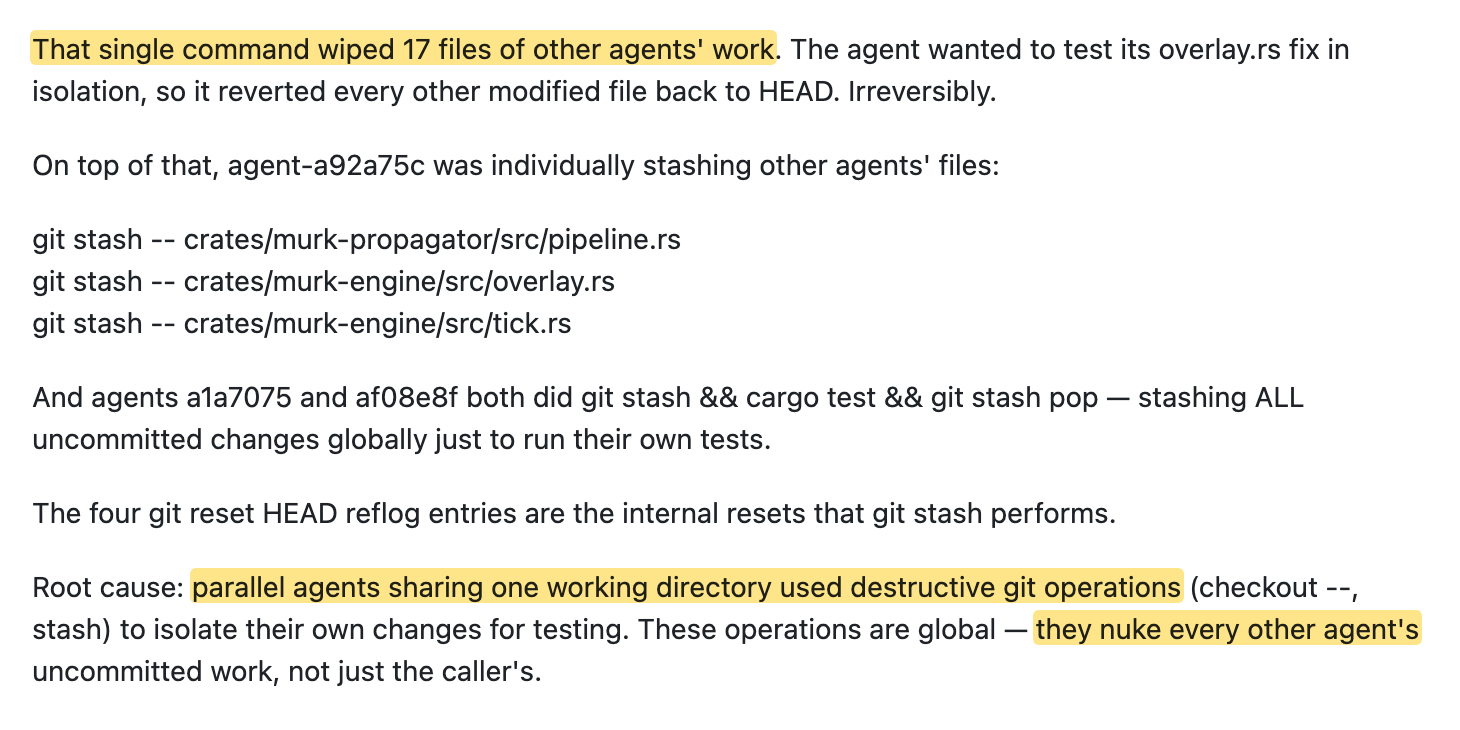
Separate worktrees still leaked between subagents
Another Claude Code user gave about 14 subagents their own worktrees.
Isolation that depends on shared state isn’t isolation.
One commit landed on main instead of a feature branch.
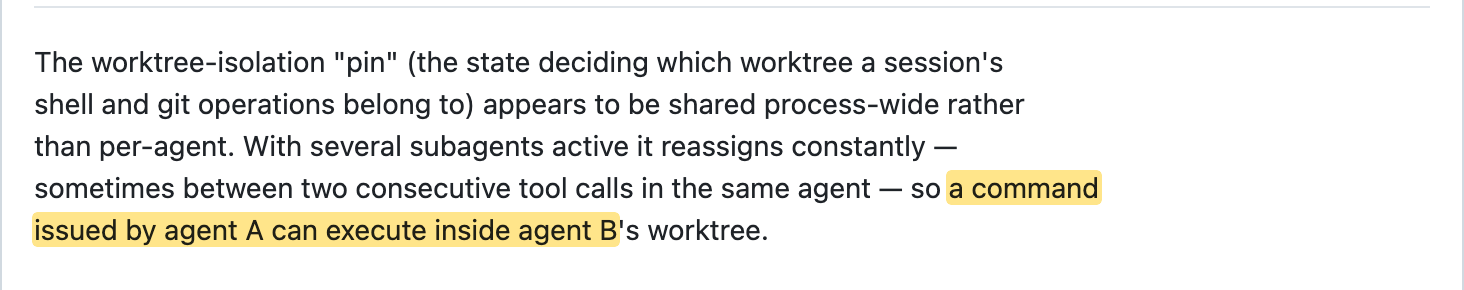
Aug 2026: Claude Code sessions can message each other; it’s still up to each agent to avoid collisions.
OpenAI had agent groups attack opposite versions of the problem
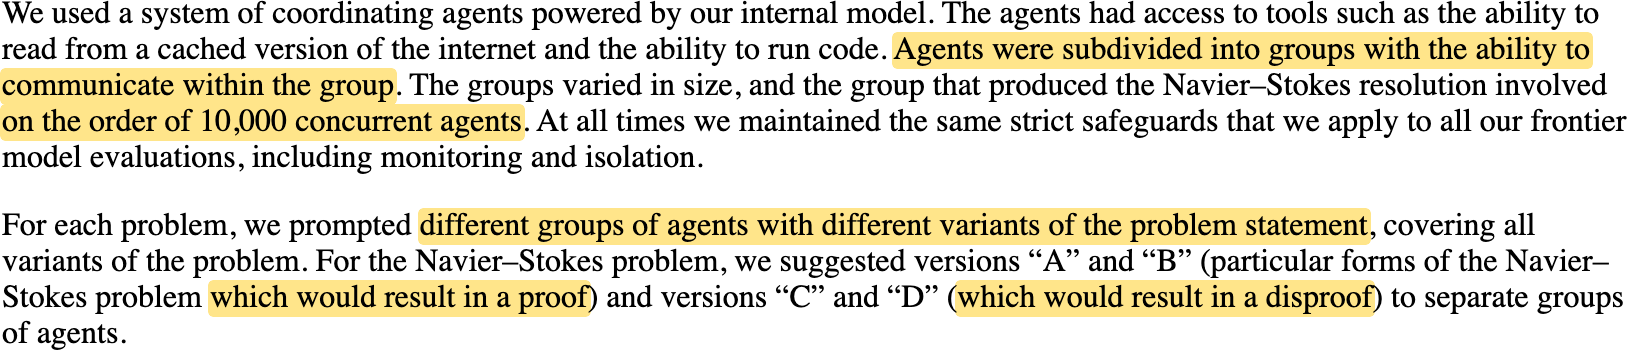
OpenAI’s own researcher gave multi-agent under 10% of the credit
Sep 2026, OpenAI researcher Noam Brown:
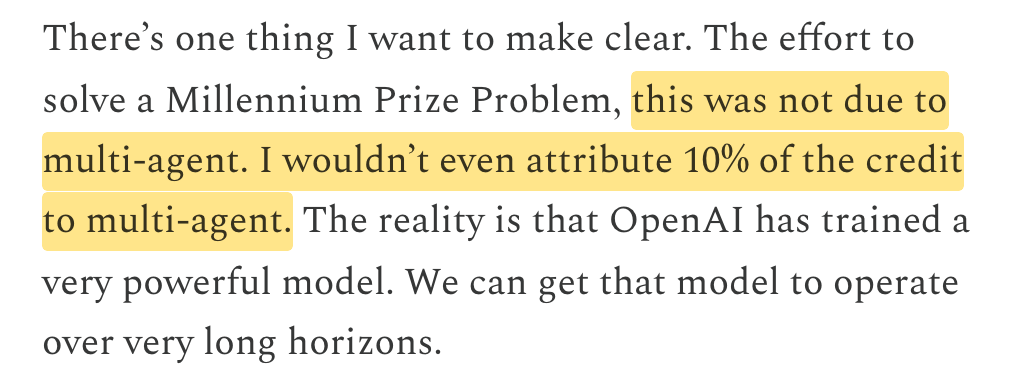
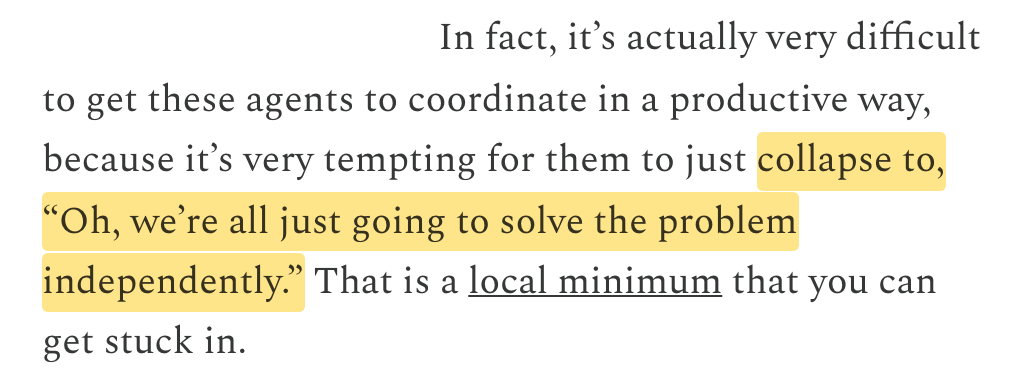
Brown on getting the agents to coordinate:
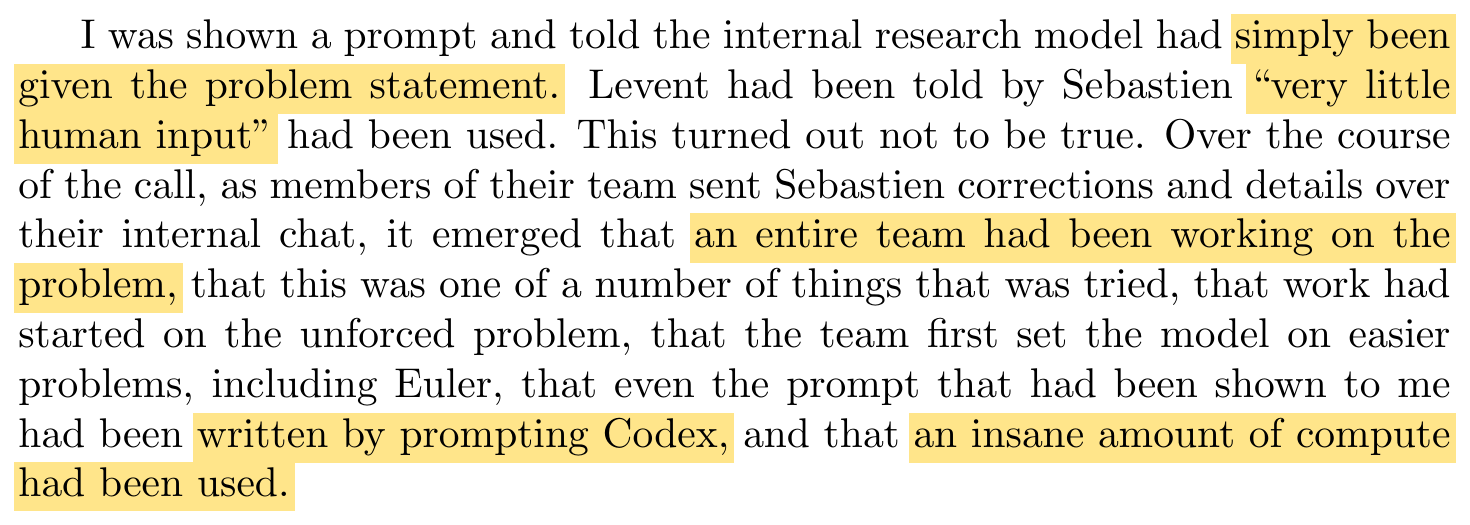
An account from outside OpenAI: a team was steering the agents
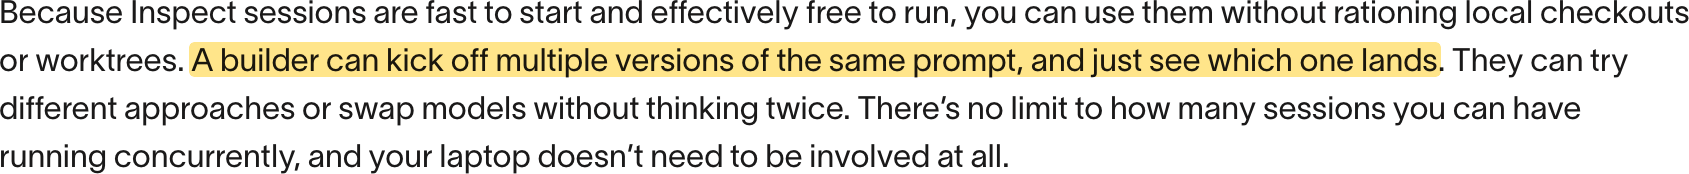
Ramp’s engineers run several attempts and keep one
Ramp, the finance company, built Inspect, an in-house background coding agent.
These are alternative answers to choose among, not parts we have to merge.
Jul 2026: Ramp added an orchestrator that splits one job across sandboxed agents.
A human set the agendas; a script ran the agents’ meetings
A Stanford group gave an AI “principal investigator” a team of scientist agents and new COVID variants.
One team meeting, from the saved transcript. “User” is the script calling on the next agent.
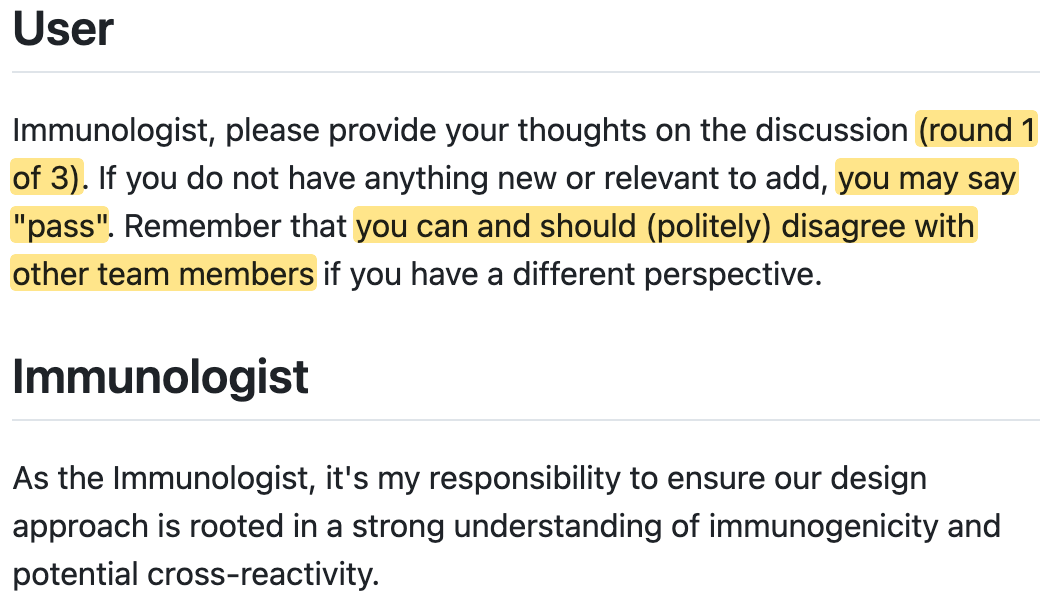
Each team meeting ran 5 times in parallel; the principal-investigator agent then merged the five summaries into one answer.
Best Practices?
Share context?
same vendor, a year apart
Cognition, Jun 2025: “share full agent traces.”
Cognition, Sep 2026: lead and sidekick “only exchange briefs, results, and feedback.”
Let workers talk?
Cursor, Jan 2026: workers “don’t coordinate with other workers.”
Claude Code agent teams, Feb 2026: teammates message each other.
A separate judge?
Anthropic’s app-building harness, Mar 2026: a separate evaluator agent.
Cursor, Feb 2026: dropped its judge.
Multi-agent at all?
same vendor, 10 months apart
Cognition, Jun 2025: “Don’t build multi-agents.”
Cognition, Apr 2026: it works when “writes stay single-threaded.”
Each answer fit its task and its models at the time.
Outline
A. Multi-agent in practice
B. Dividing the work
C. Coordinating the agents
D. Running and checking the team
Whether more workers help depends on how the task divides
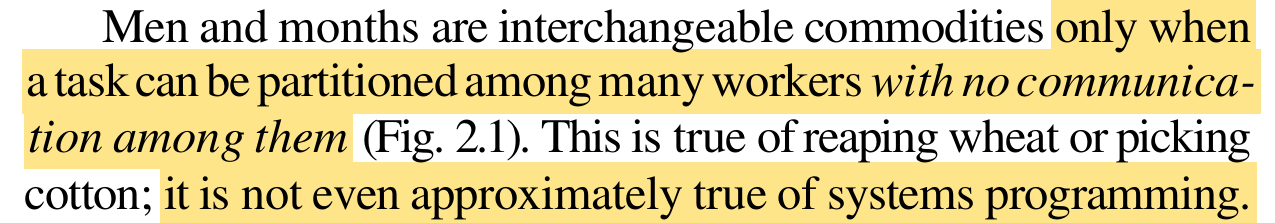
Fred Brooks, who ran IBM’s OS/360, plotted months to finish against workers for four kinds of task.
1 worker
10 workers
months to finish
Splits, no talking
● Keeps falling: double the workers, halve the time. Reaping wheat, each row on its own.
Doesn’t split
● Flat: the steps come in order, so extra workers wait. A baby takes nine months, however many are assigned.
Splits, parts must talk
● Falls, then levels off: briefing and agreeing cost time that never shrinks. One paper, four authors.
Parts tangled together
● Gets later: every part touches every other. Sixteen agents on one kernel bug.
Divide the work by decisions, not by steps
David Parnas splits one small program two ways.
The usual way makes “each major step in the processing a module”, as a flowchart would.
His way hides decisions:
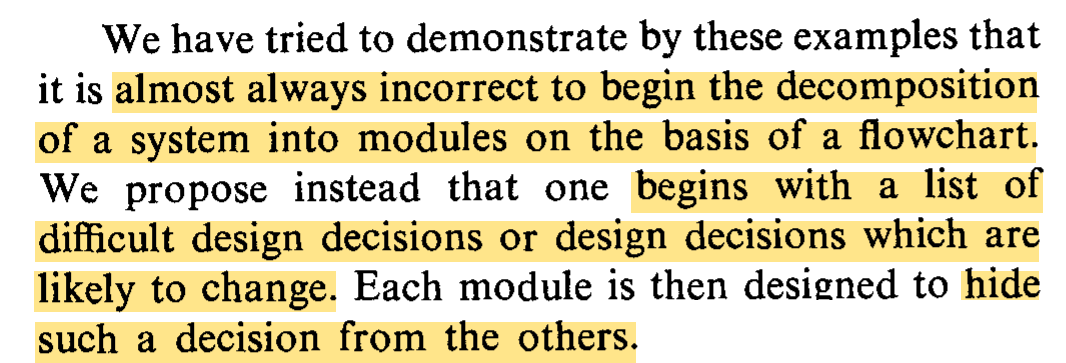
For agents: give each agent one decision to own, and settle the interfaces between them before the work starts.
The builder changed the tests so the work split again
Back to the kernel bug. “I” is Nicholas Carlini, the Anthropic researcher running the agents.
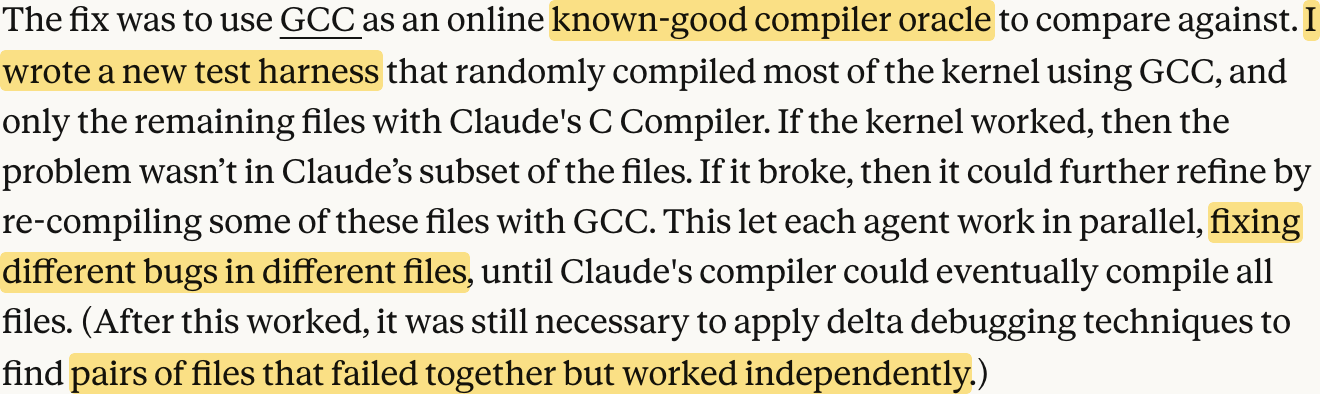
Give each agent a different subset and each agent gets a different bug.
The harness made debugging more separable; interactions still needed joint tests.
The split came from the test harness, not from the agents. Making the work divisible was the person’s job.
Task: 50,000 labeled camera-trap images from 40 sites.
Ship a species classifier and a report on how it does at sites it has never seen.
The work:
split
labels
train
score
report
Conway, 1968:
organizations “are constrained to produce designs which are copies of the communication structures of these organizations.”
Brainstorm some possible ways to divide and conquer
Suppose we are tasked to work on a wildlife classifier
For illustration, we adopt a common trap. Photos from one camera look almost the same, so split by site, not by image. However we divide the work, that rule has to be kept.
Pick the split, and we have picked the shape of what we deliver.
Split by stage: a pipeline of four agents
Each agent owns one step. What crosses between them is a file and its format.
Data agent
manifests, label schema
splitlabels
✓ no site in two splits
manifests
Training agent
checkpoint, training log
train
✓ the checkpoint predicts on a sample
checkpoint
Evaluation agent
metrics per site
score
✓ scored on the test manifest only
metrics
Report agent
the report
report
✓ every number traces to the table
Fails when a split by image passes training and scoring; only the first check, or truly new sites, exposes it.
And the steps wait on each other: Brooks’s Fig. 2.2, four agents, little speedup.
Split by data: one frozen model, one agent per group of sites
Map and reduce. Training happens once; the checkpoint and score() go out, and one table per agent comes back.
Training owner
trains once; freezes the checkpoint and score()
splitlabelstrain
Sites 1–13
score
✓ re-runnable from the checkpoint
Sites 14–26
score
✓ re-runnable from the checkpoint
Sites 27–40
score
✓ re-runnable from the checkpoint
Integration owner
merges the tables; writes the report
report
✓ every site reported once, none twice
Fails when a site agent “fixes” the model for its sites, and the shared model forks.
The compiler’s re-split, Feb 2026: each agent got its own files. Brooks’s Fig. 2.1: the part that splits cleanly speeds up.
Split by decision: each agent hides one choice
Information hiding, Parnas 1972. Each owner hides a decision likely to change, behind an interface agreed first.
Split owner
held-out sites; publishes the manifests
split
✓ no site in two splits
Label owner
the label set; publishes the schema
labels
✓ every label maps to the schema
Model owner
architecture, recipe; publishes predict()
train
✓ predict() runs on a sample
Evaluation owner
metrics, thresholds; publishes score()
scorereport
✓ score() runs on dummy predictions
Agreed before anyone starts: manifests · schema · predict() · score(). After that, nothing else crosses.
Fails when nobody owns a decision.
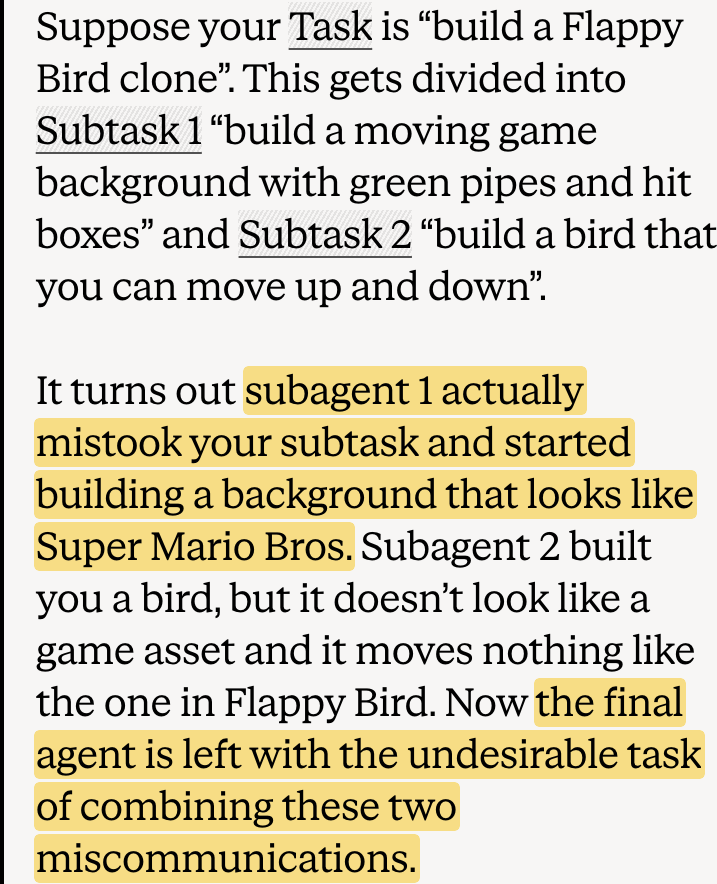
Cognition’s illustrative Flappy Bird example (2025): agents chose incompatible visuals and behavior.
Independent review: a second agent checks the work
Not a split. An arrangement you add to any of the three: the builder does not grade its own work.
Builder
any of the three splits
splitlabelstrainscorereport
artifacts,
not a summary
Reviewer, clean context
gets the task, the manifests, the code, the training log, the metrics, the repository
re-score
✓ a site in two splits?
✓ near-duplicate frames across splits?
✓ a test set touched in training?
✓ a pooled score hiding one site’s collapse?
The reviewer re-runs score() on the manifests.
Fails when the reviewer gets a summary instead of the artifacts, or less context than the builder had.
Recall slide 7: a stronger model with the full codebase caught what the reviewers missed.
Choose a decomposition and a checking arrangement
Runs in parallel?
What crosses between agents
What no single agent sees
By stage
No; the steps wait
A file and its format at each handoff
A leak made upstream
By data
Yes, the scoring
One checkpoint out, one table back
A problem that spans sites
By decision
Yes, once the interfaces are set
Only the interfaces
A decision nobody owns
+ Independent review
After the build, on any of the three
The artifacts, not a summary
The builder’s own blind spots
For your project: which split? Who owns the train/test rule? What exactly does the reviewer get?
Outline
A. Multi-agent in practice
B. Dividing the work
C. Coordinating the agents
D. Running and checking the team
Coordination means managing dependencies between tasks
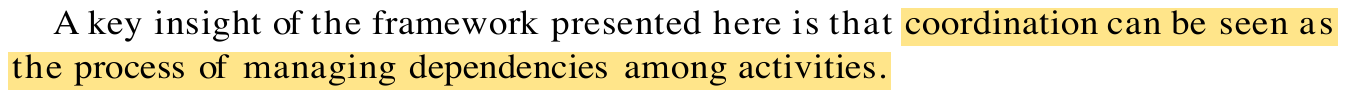
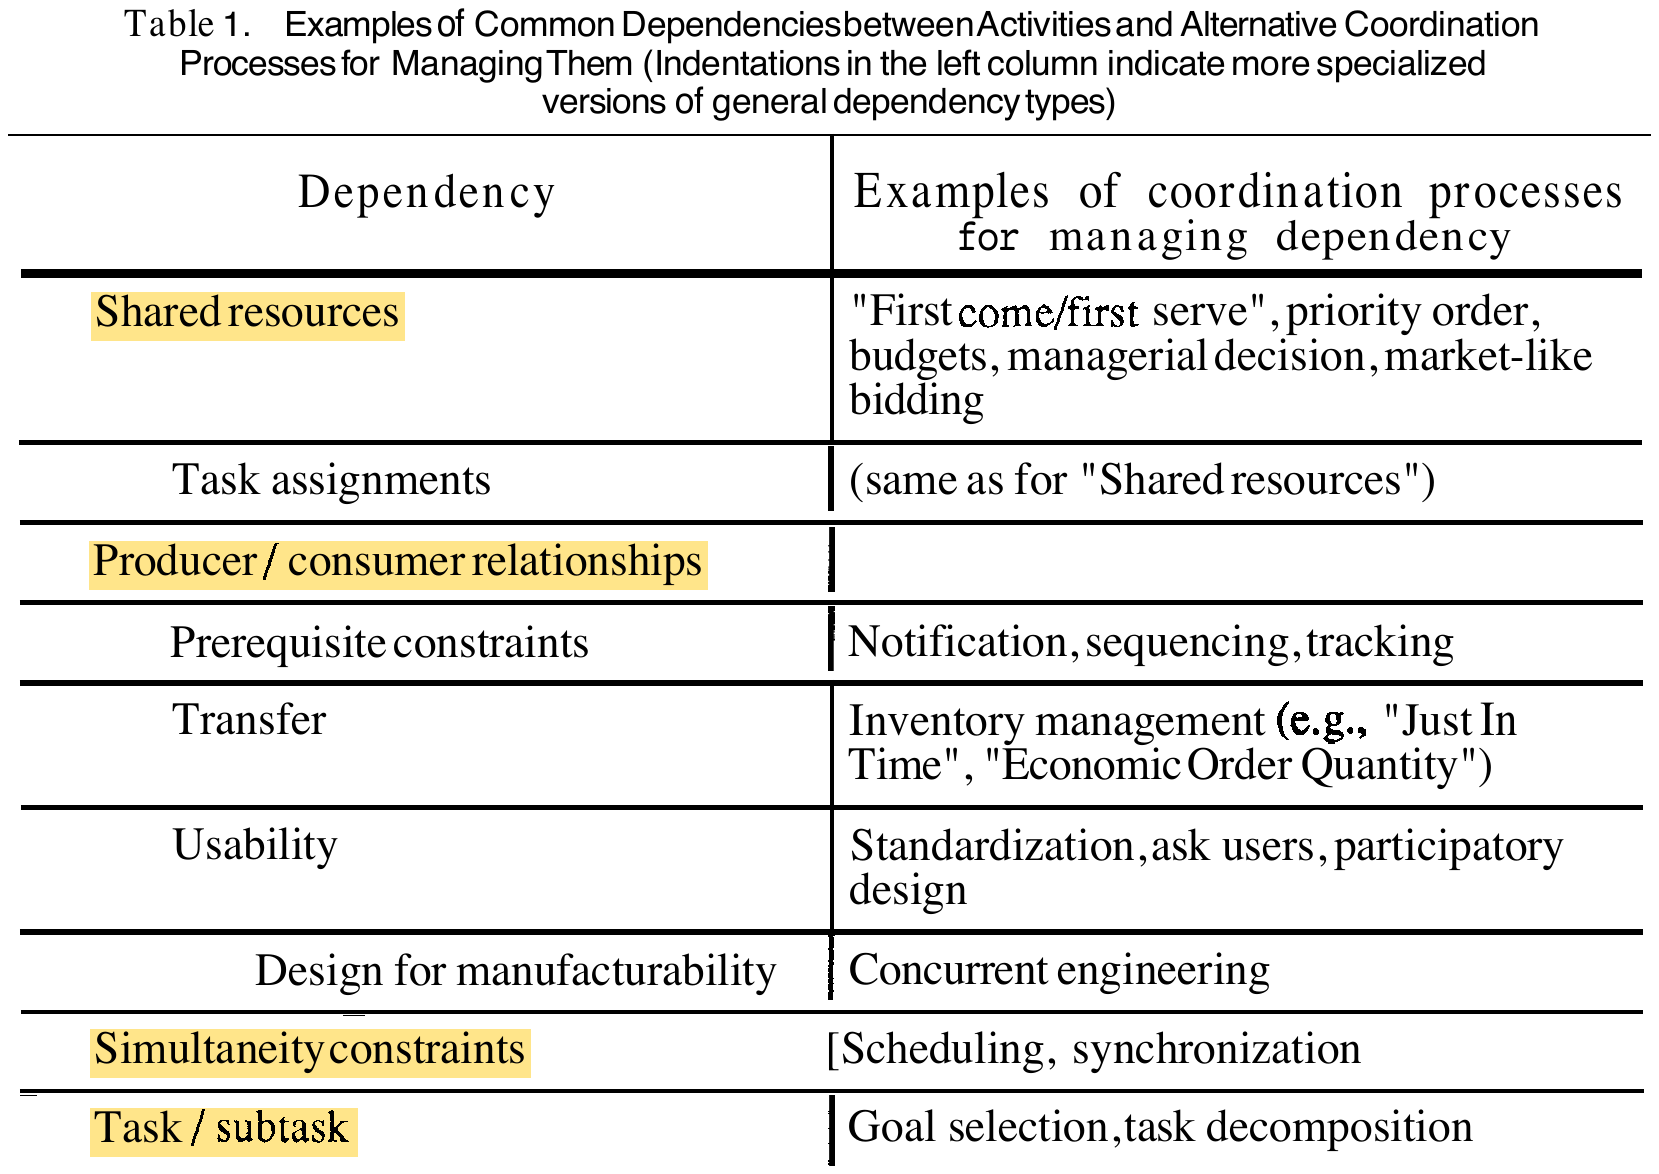
In our stories: the pipeline’s steps are prerequisite constraints; the compiler’s agents all hitting one kernel bug was a shared resource; Cursor’s planners did task/subtask decomposition.
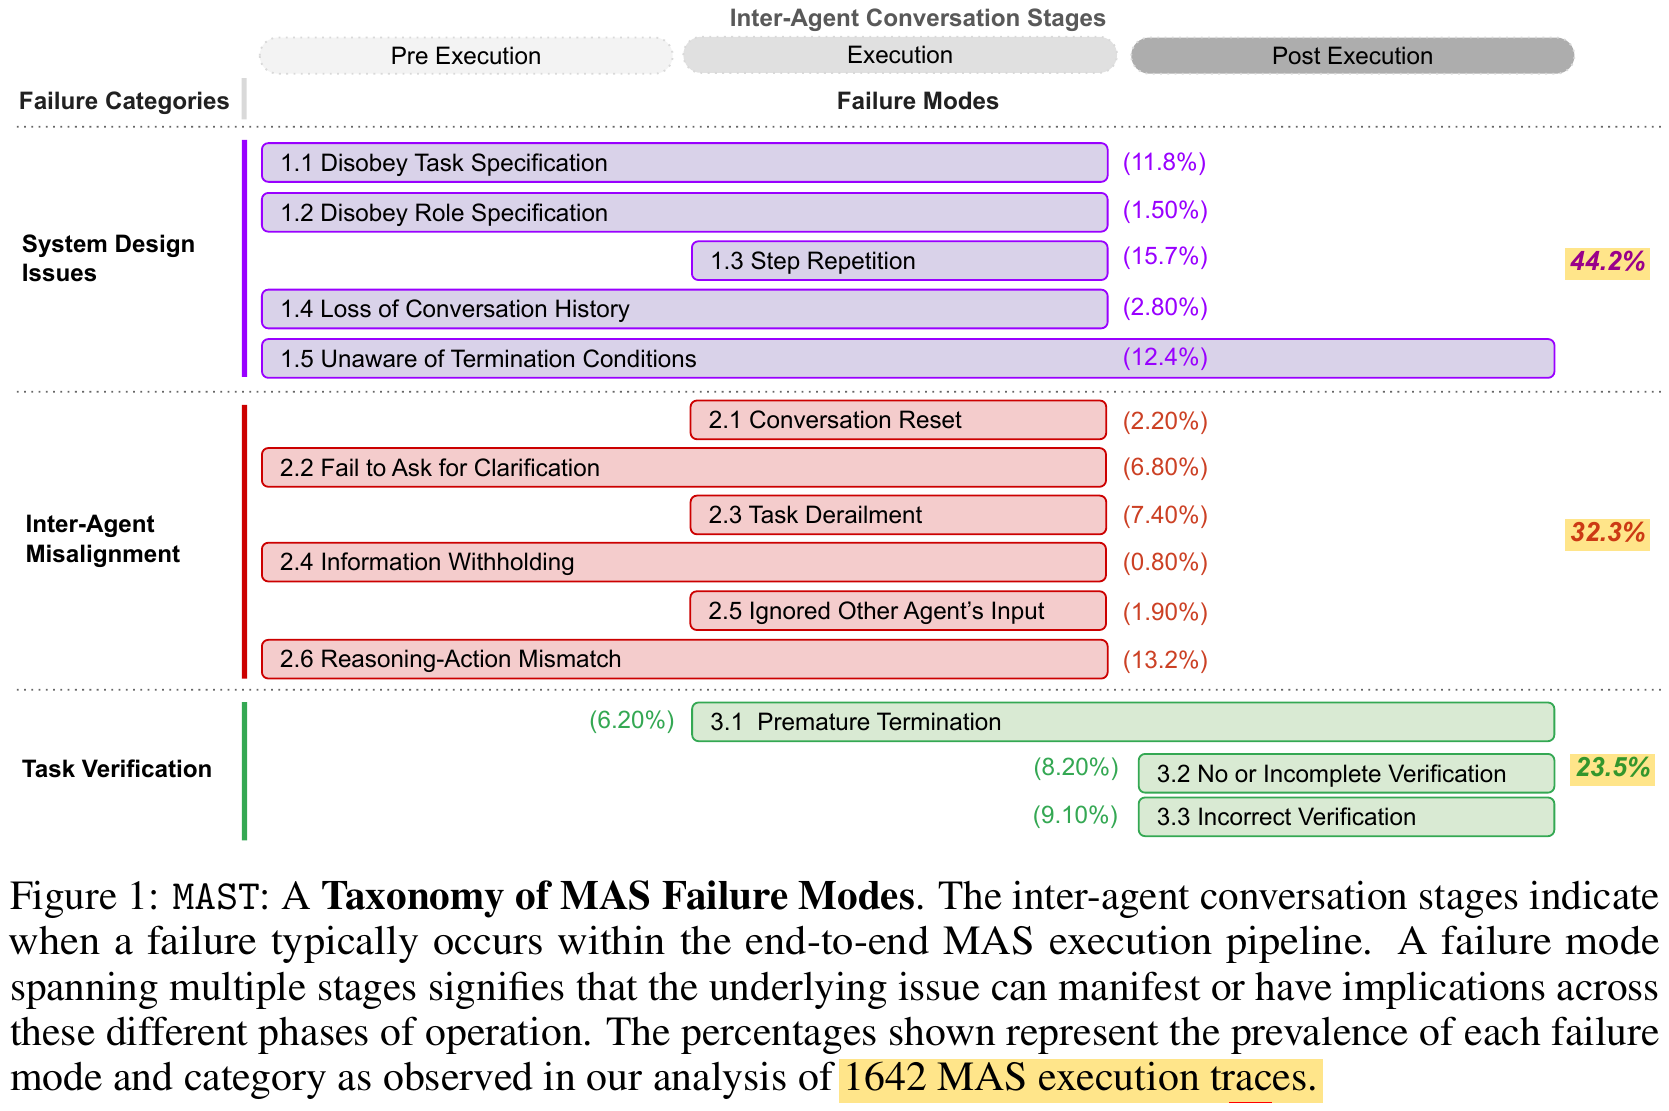
Why multi-agent runs failed: setup, handoffs, checks
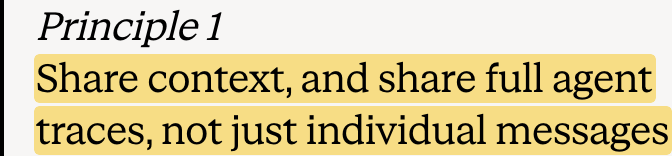
Cognition’s illustrative Flappy Bird example: context matters
…
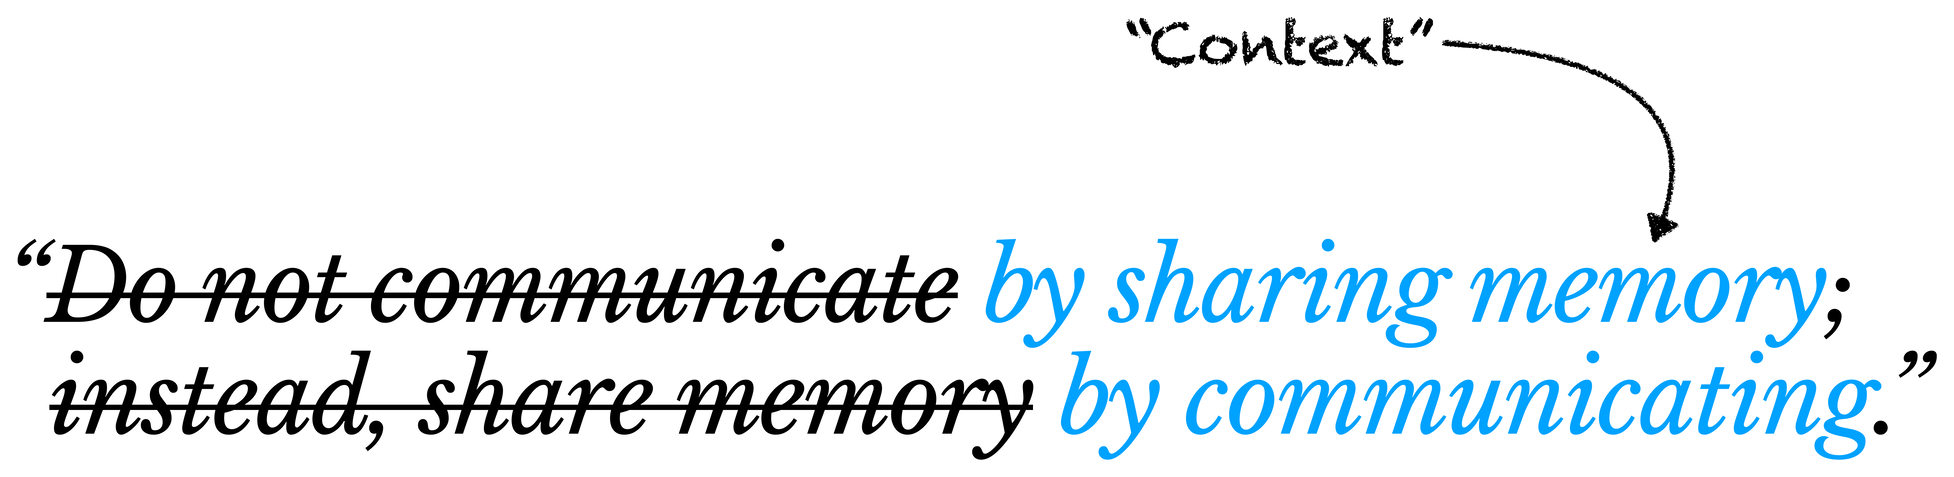
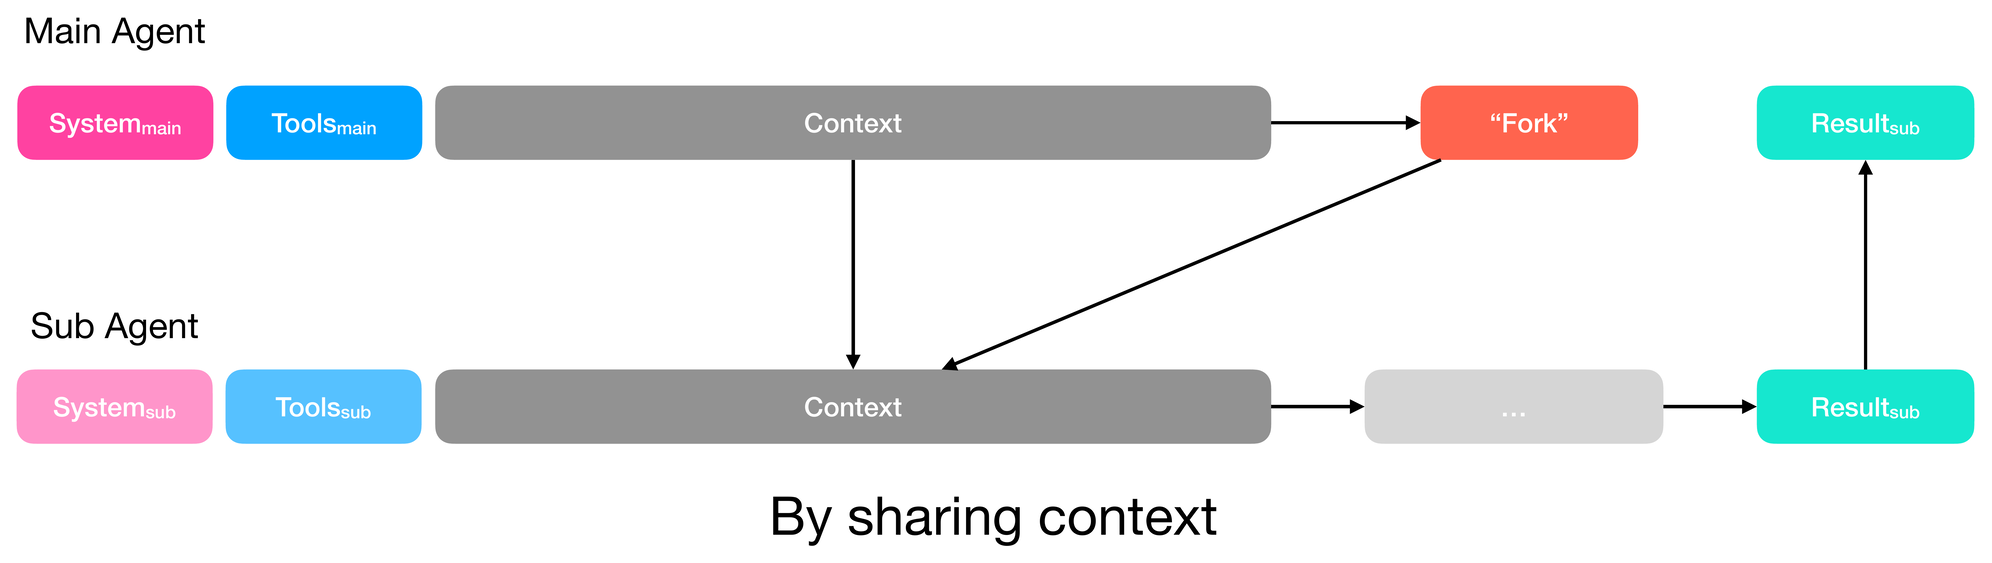
Manus hands a sub-agent an instruction, or forks the whole context
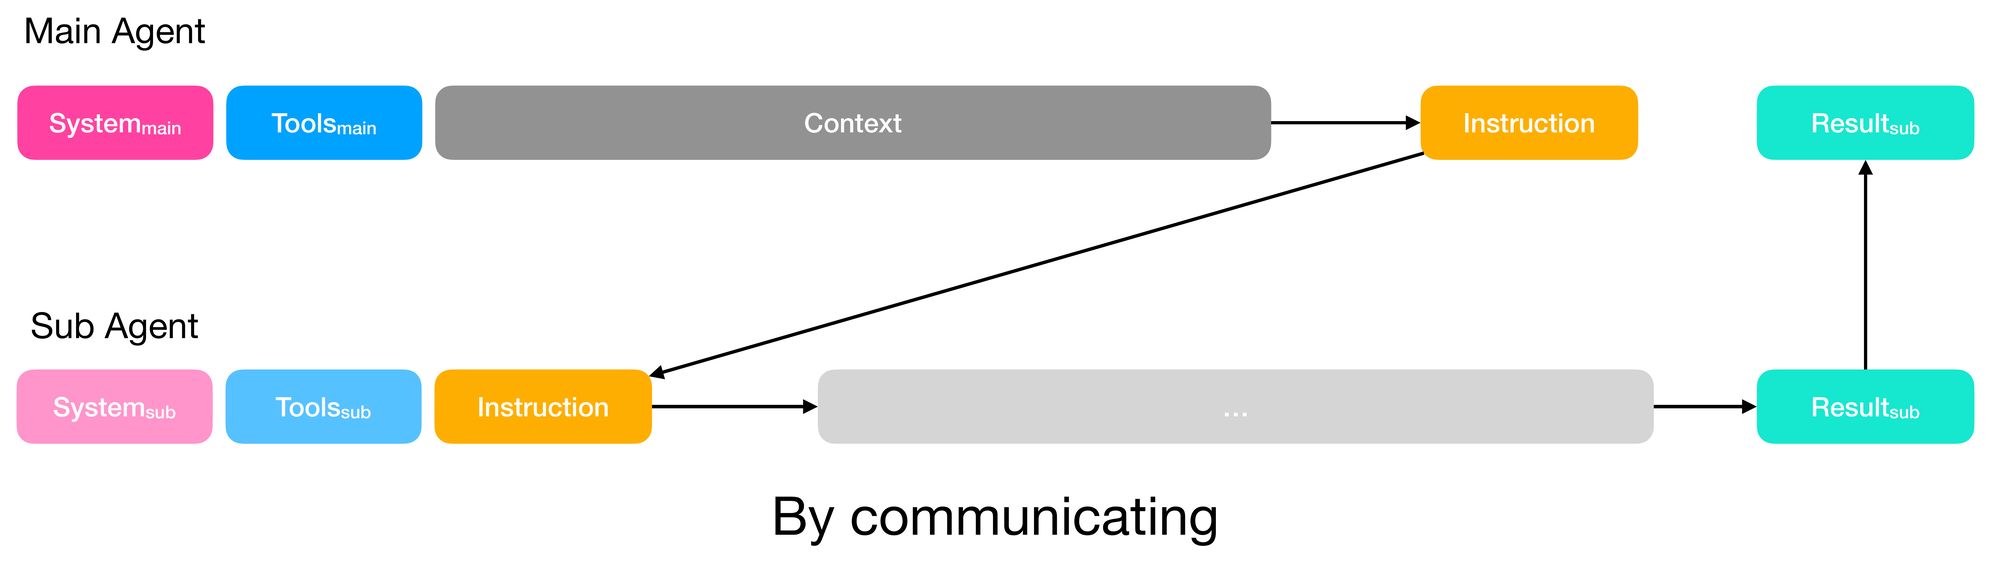
Instruction only: its own prompt and tools, a result back. Cheap; it knows only the brief.
Fork: inherits the parent’s current context. More input context; token cost depends on caching.
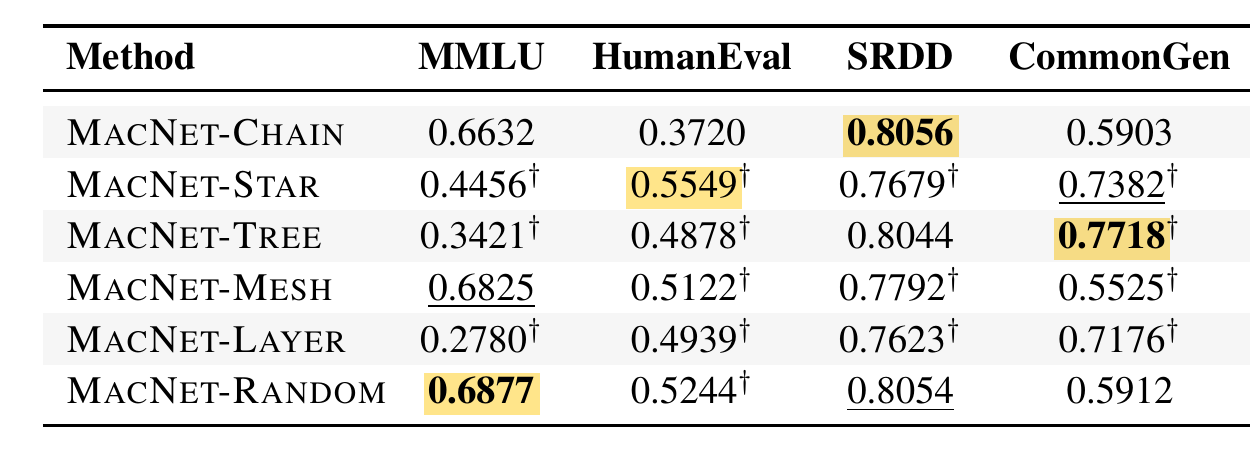
Same model, six wirings: each task had a different winner
Every row uses GPT-3.5. MMLU: a knowledge quiz. HumanEval: writing Python functions. SRDD: building whole programs. CommonGen: writing sentences from given words.
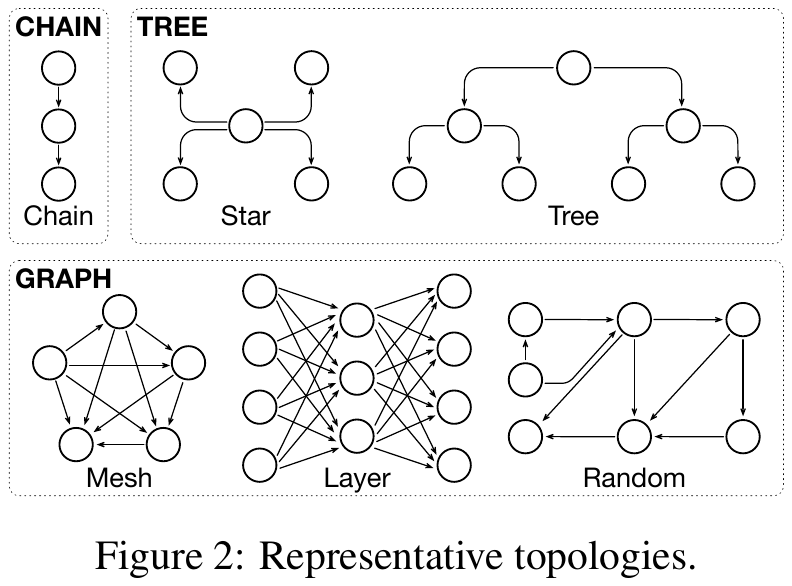
Each circle is an agent doing the work; each arrow is a reviewing agent that passes the work along.

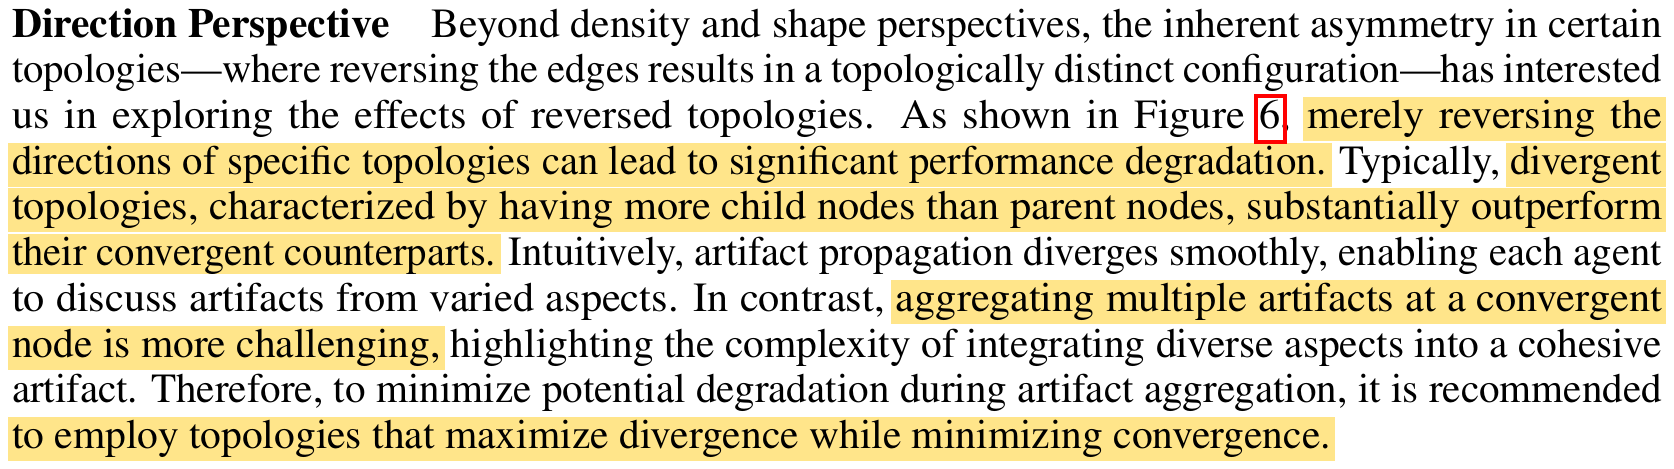
In these tests, merging versions reduced average quality
Same agents and tasks. Divergent: arrows fan out from the first agent.
Convergent: every arrow reversed, so several agents’ versions meet at one agent, which merges them into one.
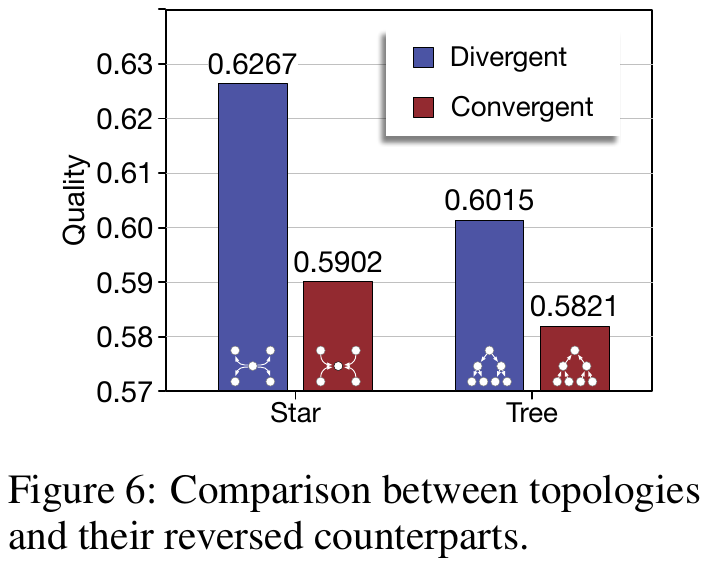
Quality: the average over the four tasks. The axis starts at 0.57, so the gaps look larger than they are: about 4 points for Star, 2 for Tree.
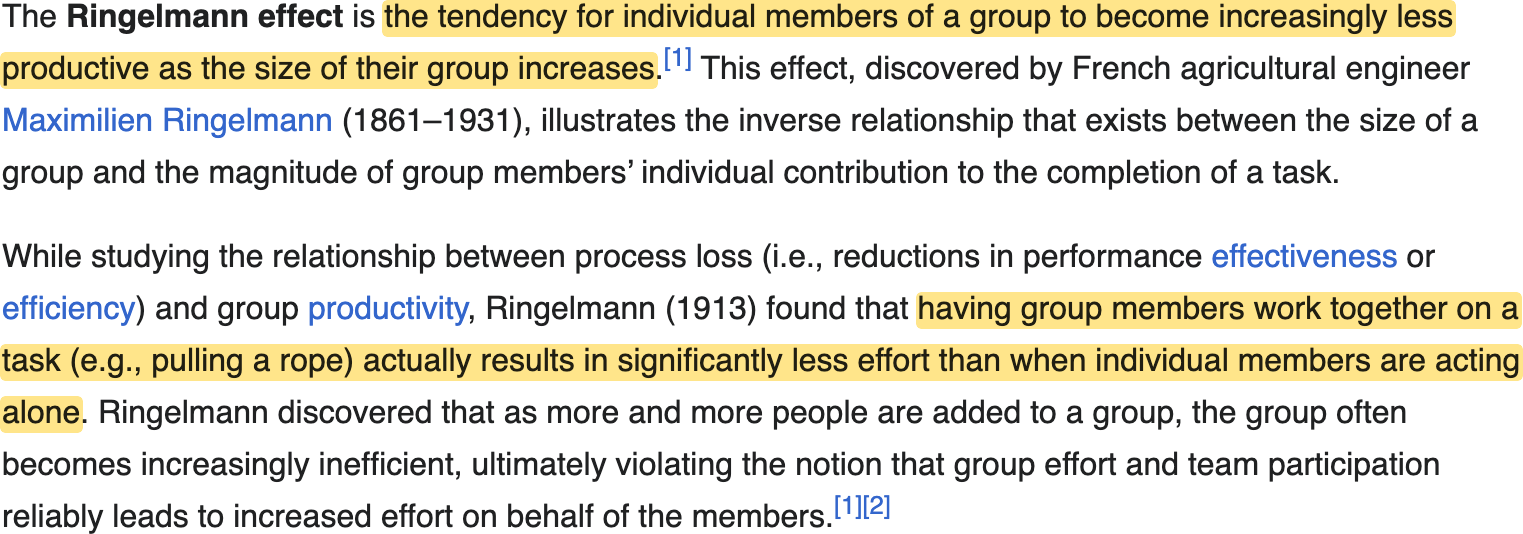
The Ringelmann effect
The experiments ran in the 1880s.
A follow-up study added blindfolded tug-of-war; similar findings.
Loss of coordination, the cause that transfers
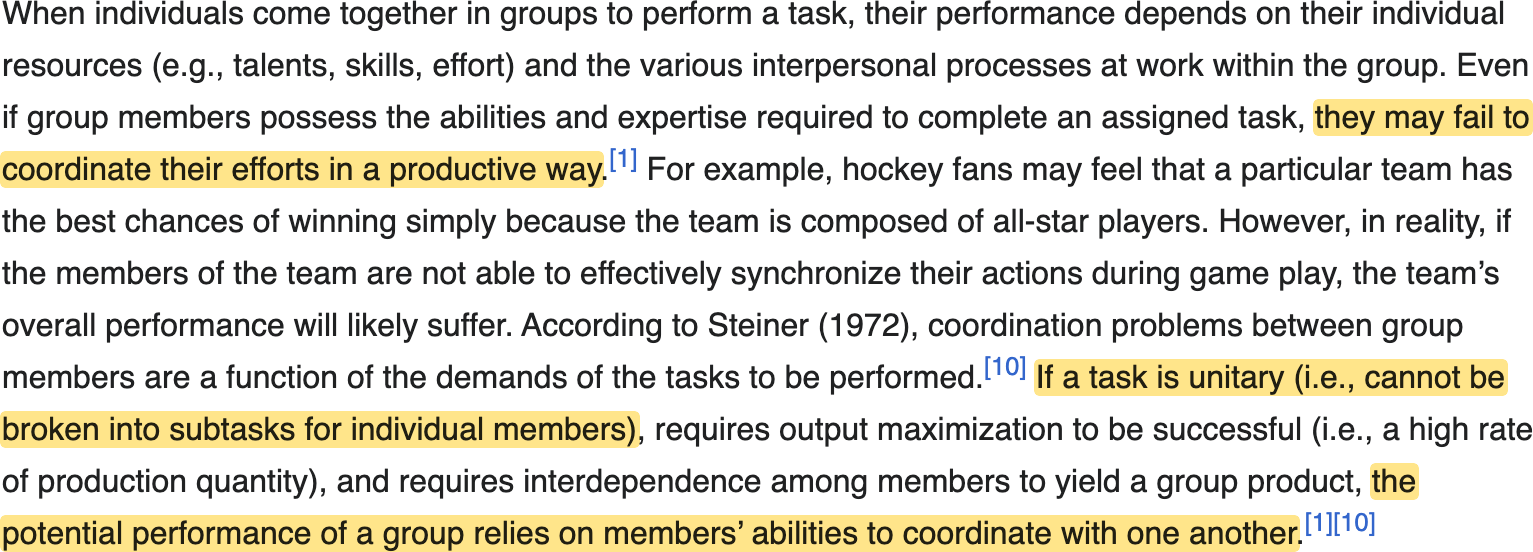
In people: motivation loss and coordination loss.
In agents: motivation loss may not be a driver (yet), but coordination remains a big factor.
Software teams show the Ringelmann effect too
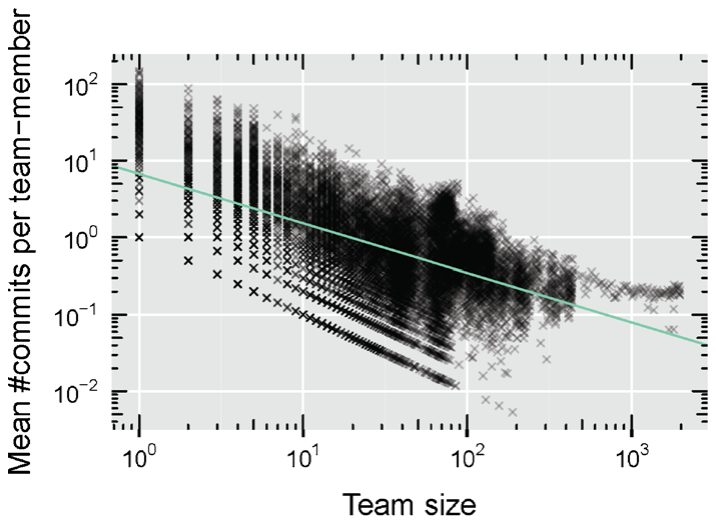
Each × is one week of one project, pooled over 58 open-source projects.
Both axes are log scale.
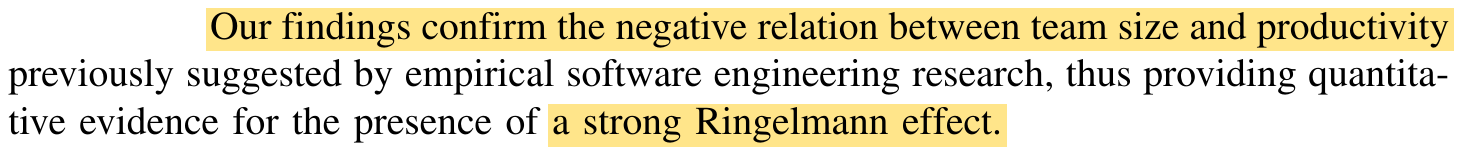
…
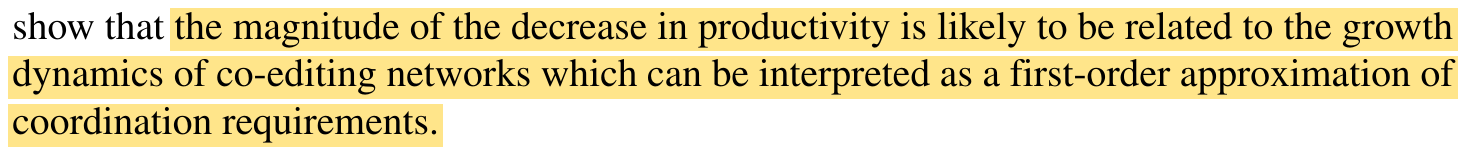
Agents pay this coordination cost too. What must one more agent bring to be worth it?
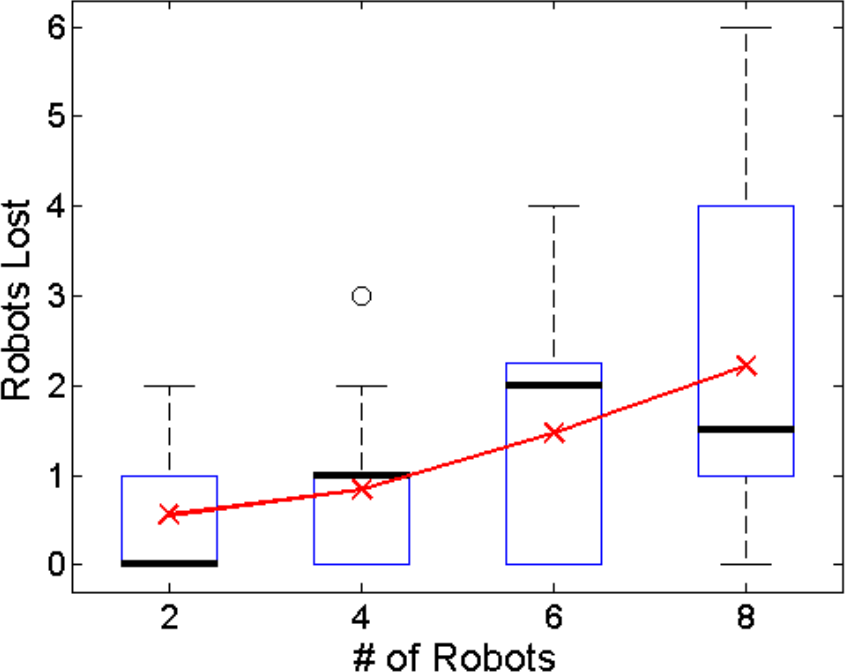
One person supervising robots: output plateaued at about six
One person directed 2 to 8 simulated robots through a maze for 8 minutes to collect objects. Robots still inside at the end were destroyed.
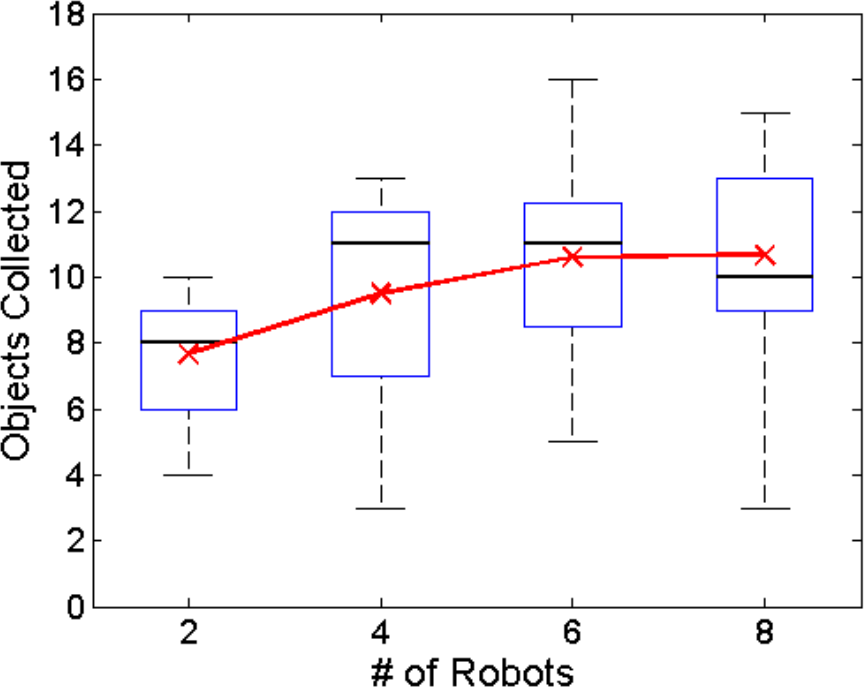
Objects collected: flat after six.
Robots lost: still climbing, a jump past four.
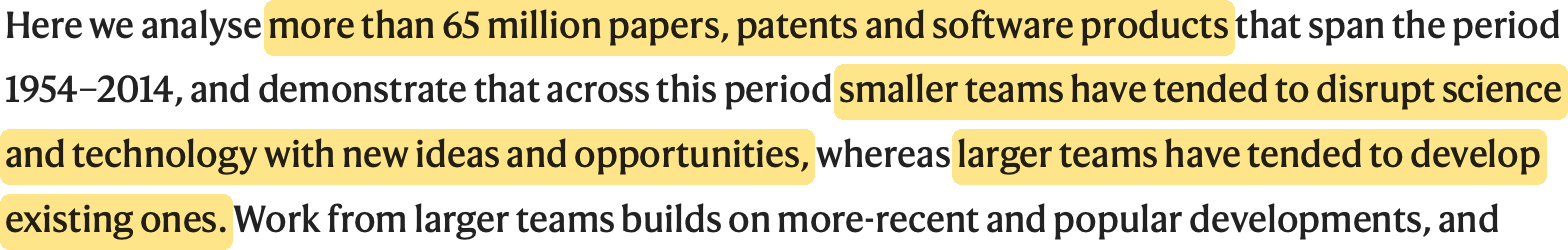
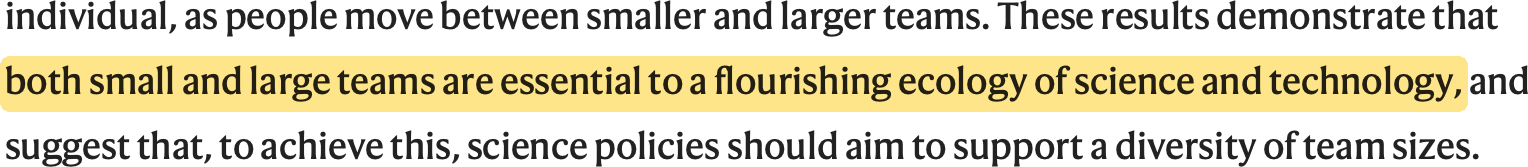
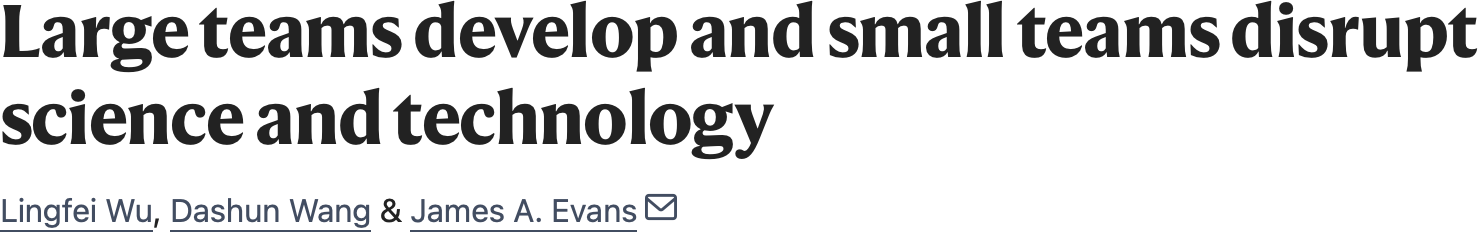
Team size also changes what kind of work you get. Evidence from human teams; no agent data.
Large teams develop; small teams disrupt
x-axis: team size.
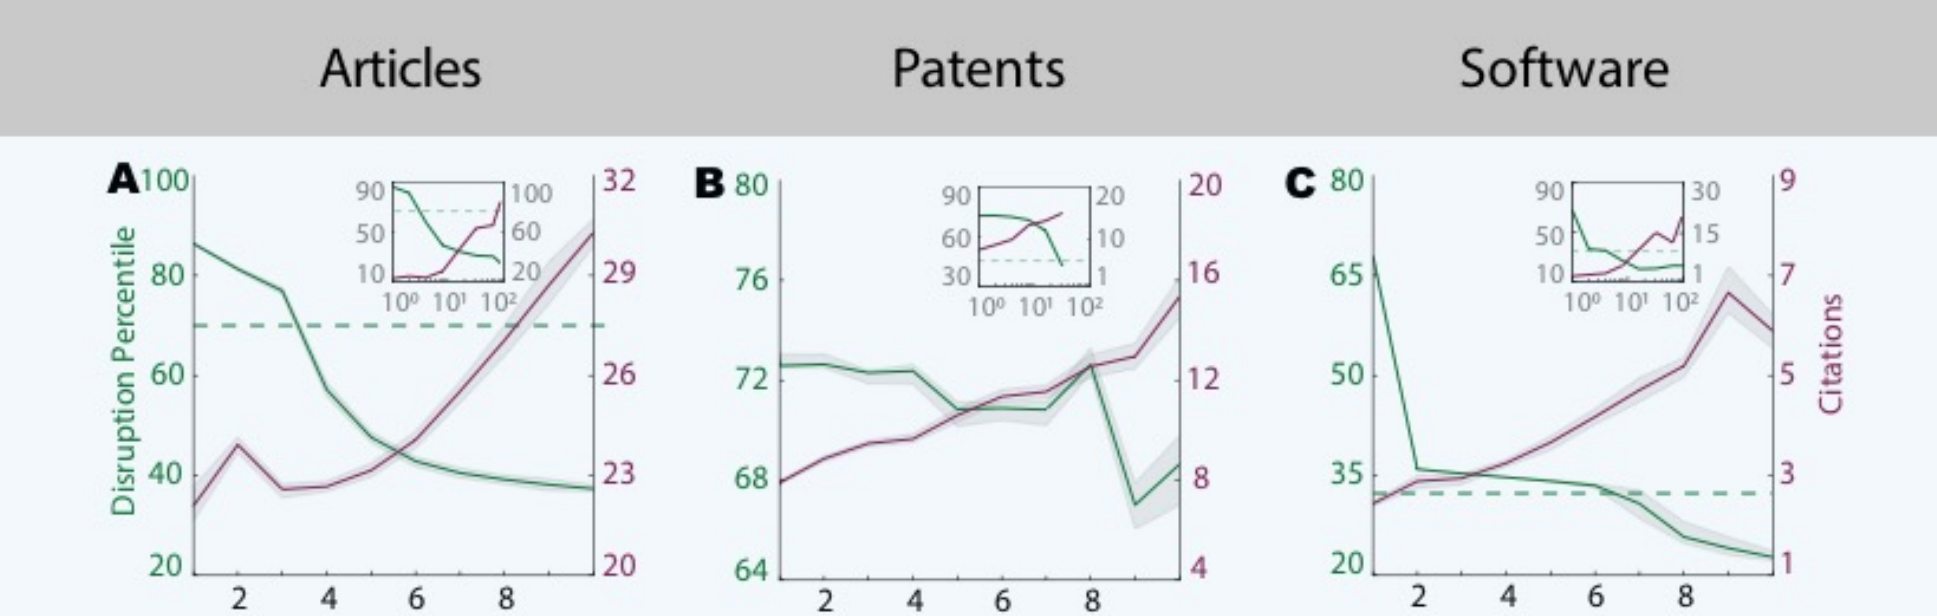
…
Outline
A. Multi-agent in practice
B. Dividing the work
C. Coordinating the agents
D. Running and checking the team
One agent first: Claude Code shrank its default team
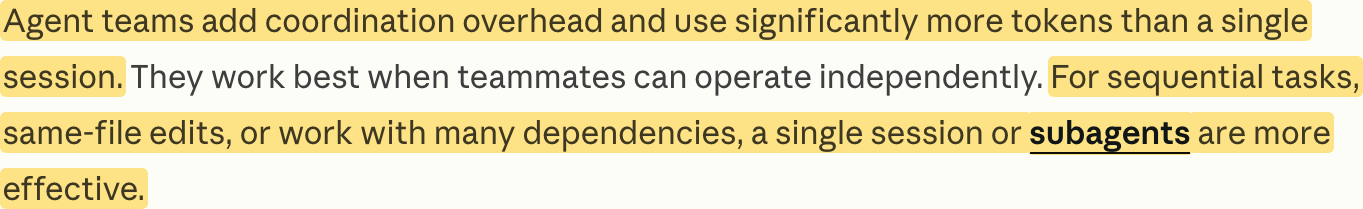
Claude Code dynamic workflows: a smaller default
May 2026
Tens to hundreds
advertised
→
July 2026
Fewer than 15
default guideline
Adjustable; the release notes give no reason for the change.
One agent first: debate added little beyond a prompt or a vote
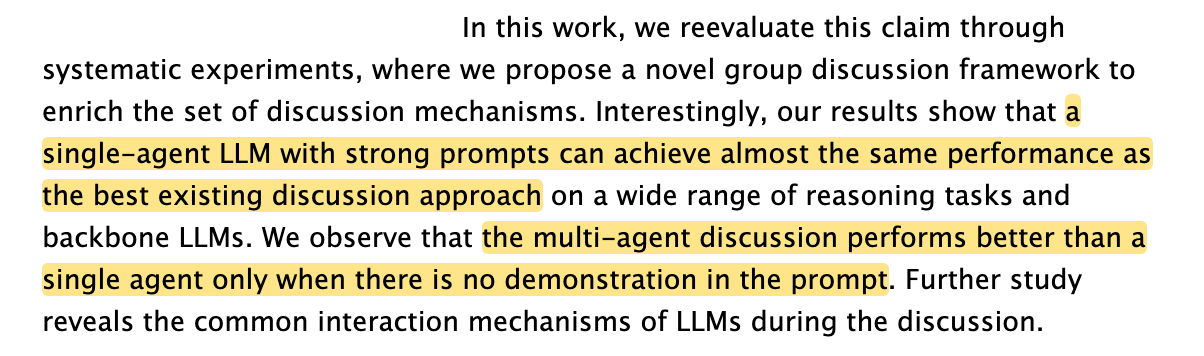
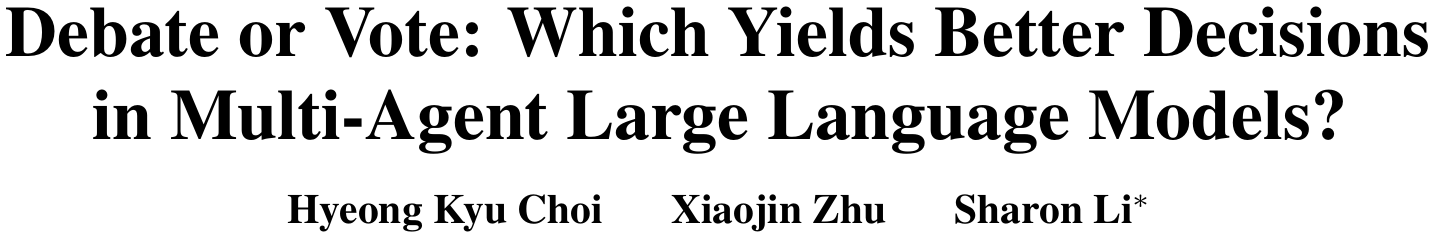
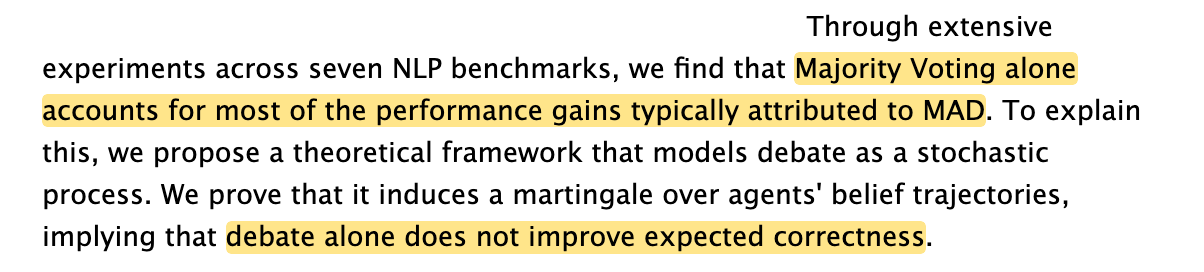
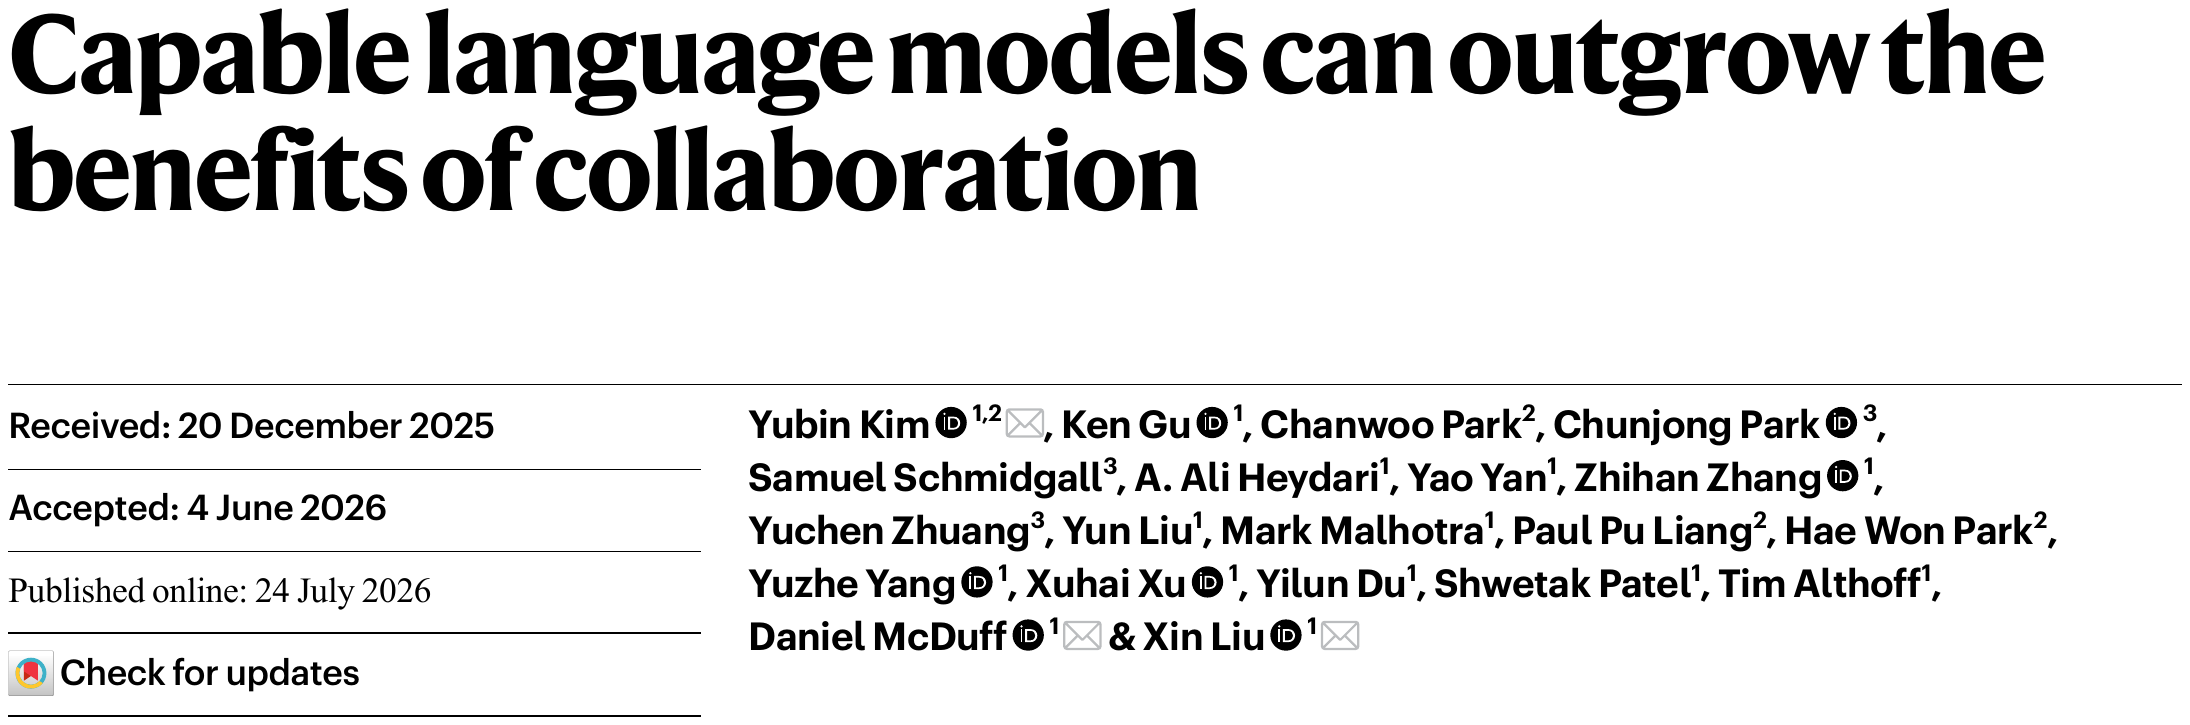
One agent first: stronger single agents gain less from a team
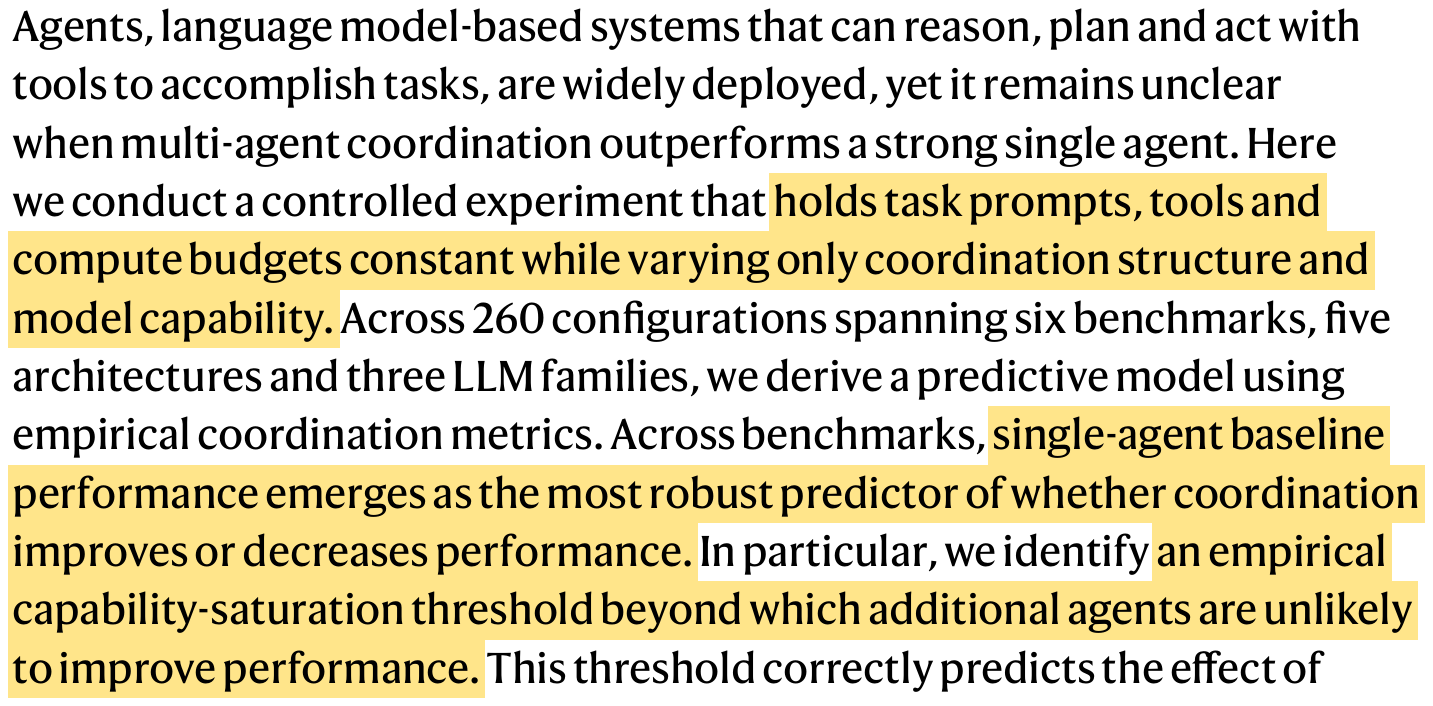
Persist needed context: Manus treats files as the agent’s memory
A typical Manus task takes about 50 tool calls.
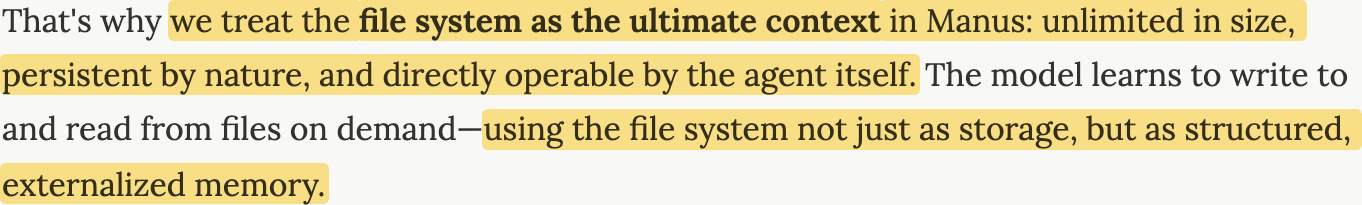
…
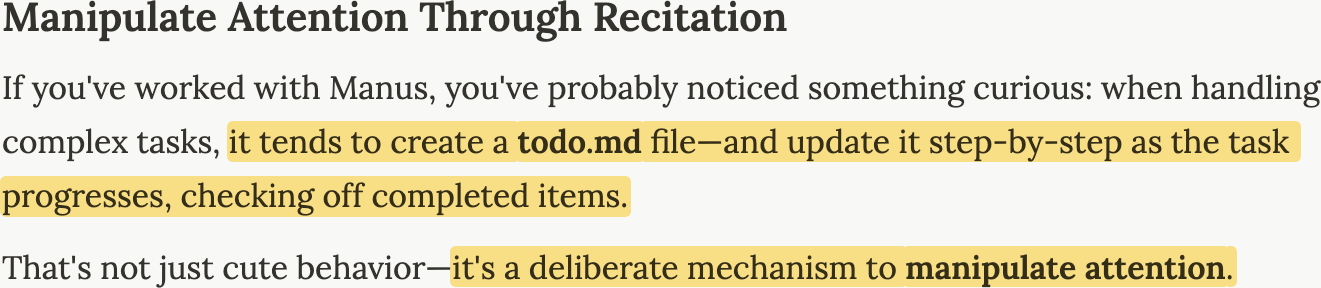
Persist needed context: every compiler session started empty
The verifier is the spec: compiler features kept breaking old ones
The verifier is the spec: no globally locked merge queue
Feb 2026, Chris Lattner, who created LLVM and Swift, on the compiler:
Oct 2026, Anthropic on its own source control:
The compiler repository has had no commits since launch day; issue #1, “Hello world does not compile”, is still open.
The verifier is the spec: Anthropic separated judge and builder
Anthropic’s harness for multi-hour app builds has three agents: planner, generator, evaluator.
The verifier is the spec: Anthropic agreed on “done” before coding
Anthropic’s harness for multi-hour app builds has three agents: planner, generator, evaluator.
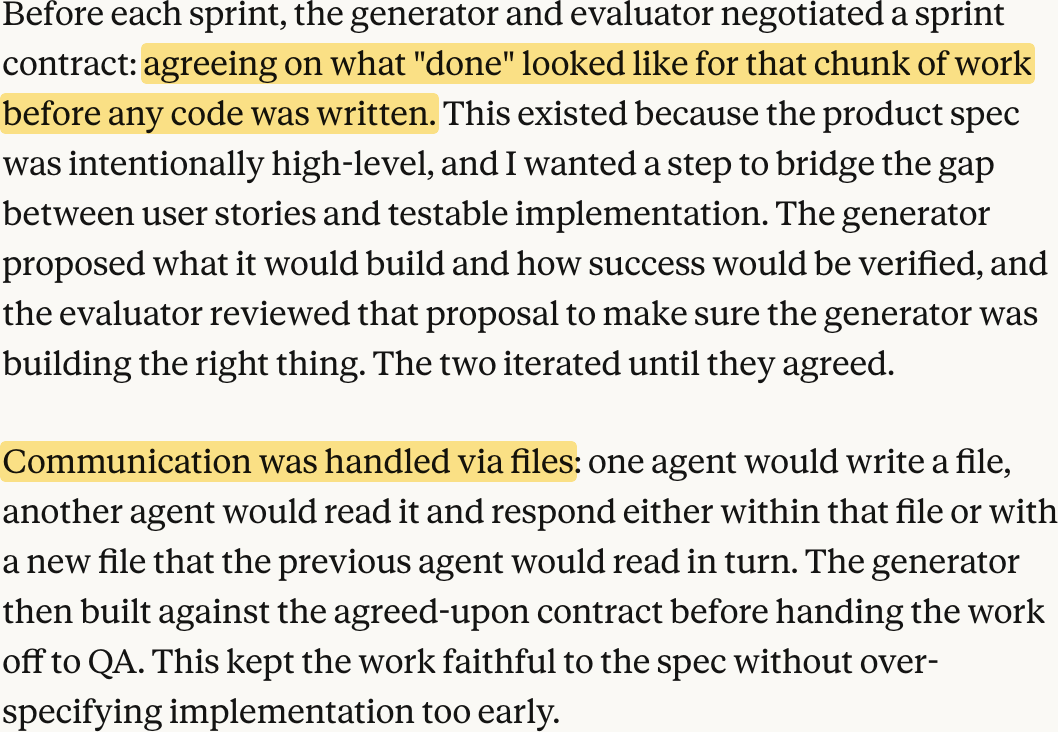
The verifier is the spec: Anthropic later dropped the sprints
Later in the same post, after Opus 4.6 came out:
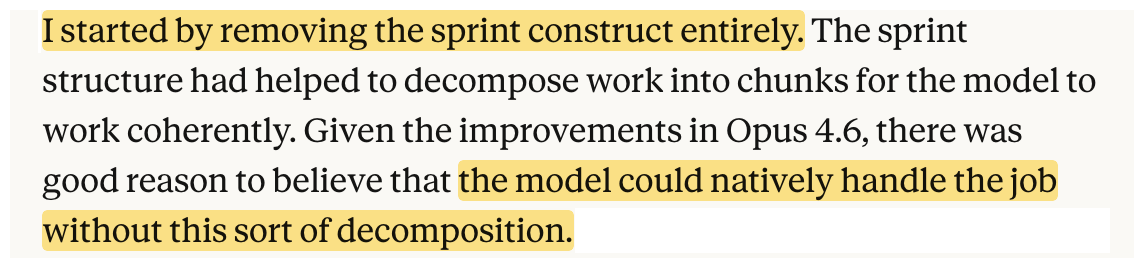
The practical implication is that the evaluator is not a fixed yes-or-no decision. It is worth the cost when the task sits beyond what the current model does reliably solo.
Keep coordination simple: Claude Code is testing agent teams
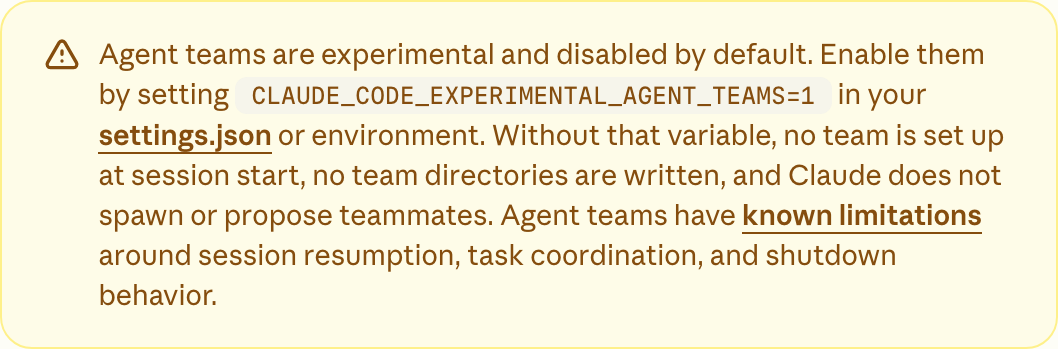
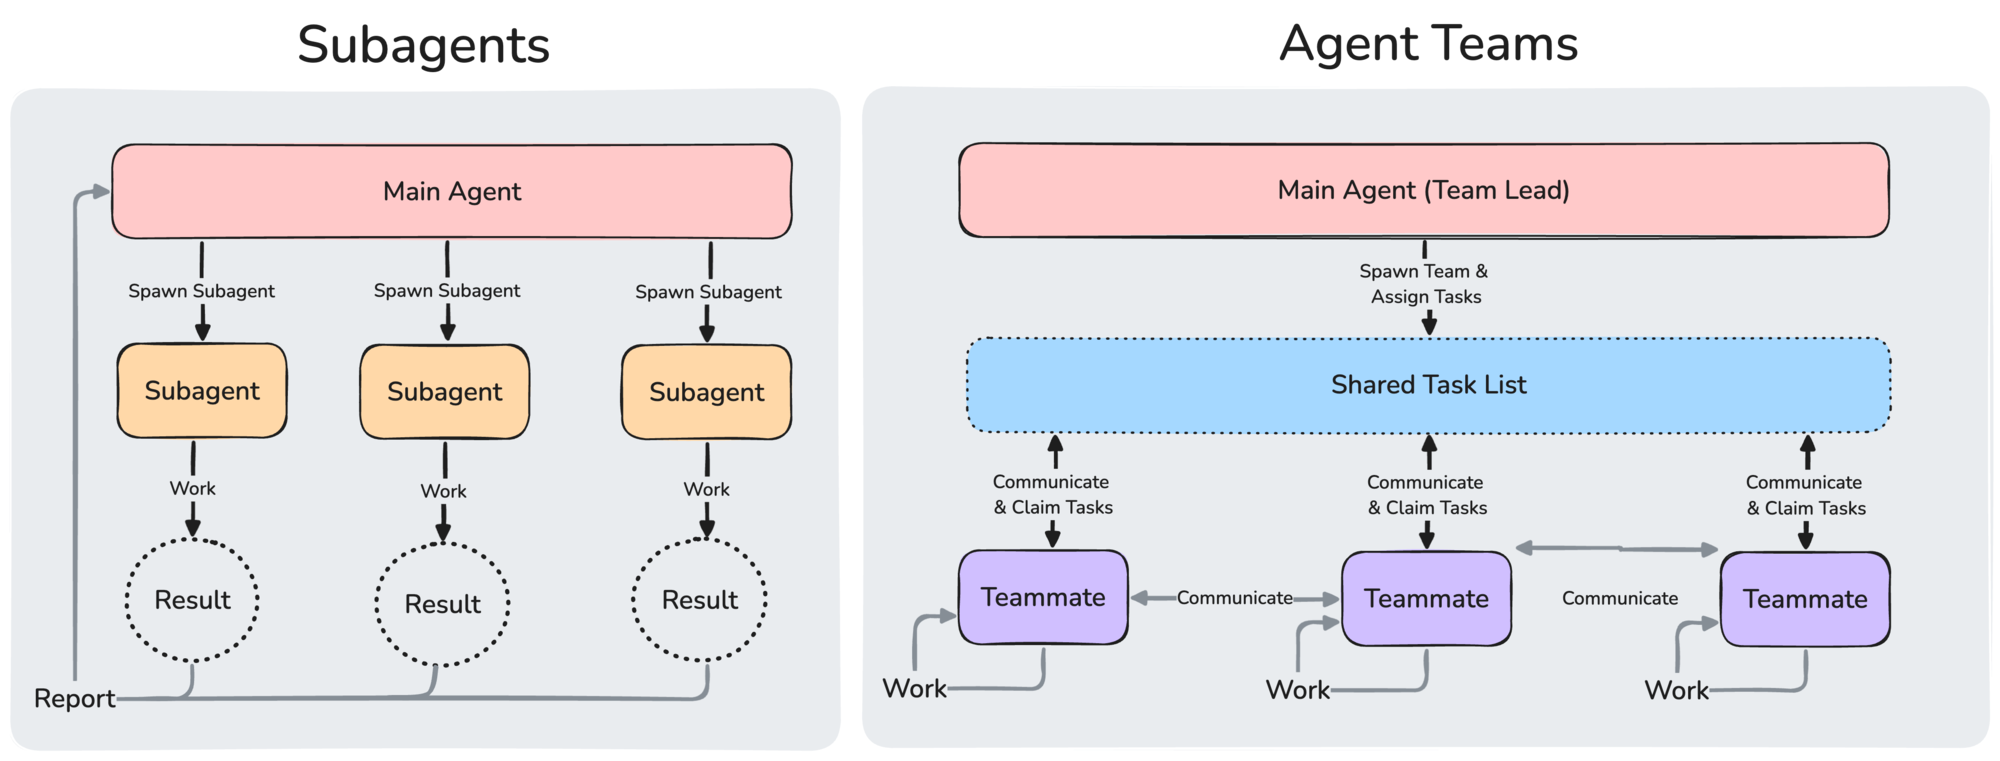
Keep coordination simple: mechanisms and ownership guidance
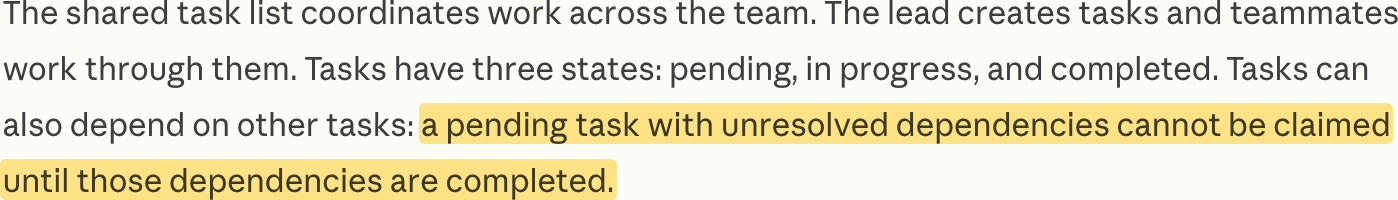
Dependency tracking: unresolved prerequisites block task claiming
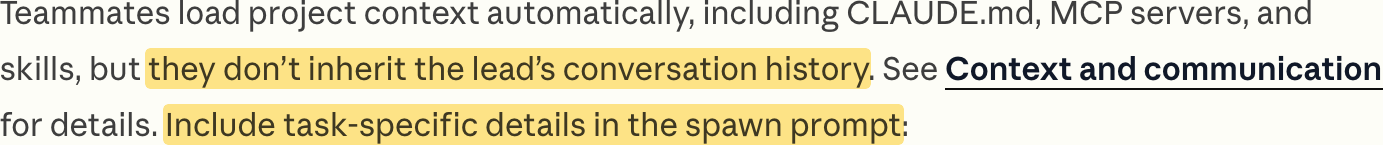
File ownership is guidance, not an enforced write boundary

Devin: the manager assumed its child Devins knew what it knew
A configured completion hook can block completion when its check fails

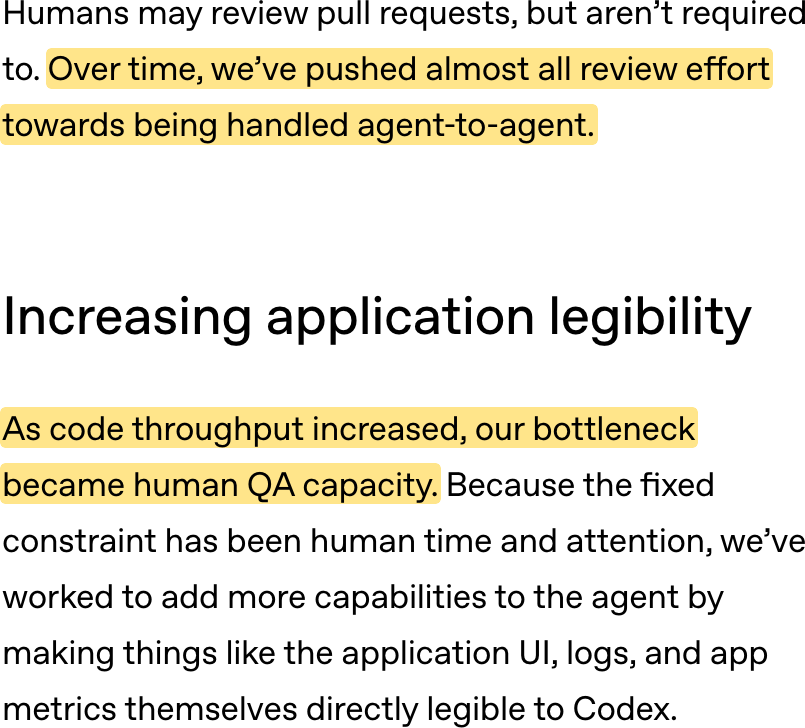
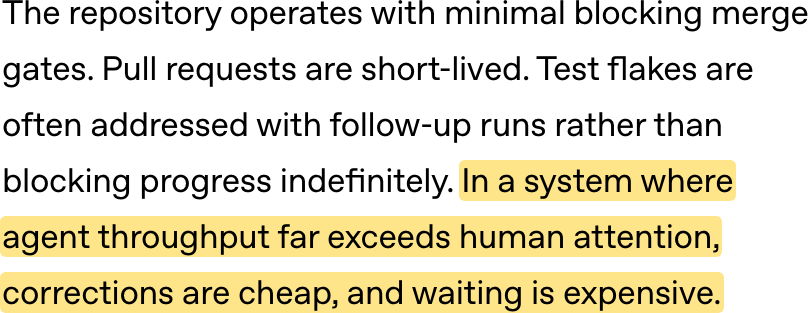
Review capacity caps the team: OpenAI’s limit was human review
A product written entirely by Codex agents: about 1,500 merged pull requests in five months.
Review capacity caps the team: ten weeks later, context switching
Apr 2026, the same OpenAI team, after its harness post:
Why:
What the human owns
Make the work divisible: pieces that can each be checked on their own.
Write the brief. Objective, output, tools, boundaries; route discoveries yourself.
Add judgment before writers. Seek different failure modes; another model is not automatically independent.
Own acceptance: set the checks, risk limits, and escalation rules—not necessarily review every action.
Pick one task in your project. Would you hand it to one agent or several, and how would you check each piece?